

Sakupljač feed-ova
Futures of Maths Launch
[This is a guest post by Francesco Fournier-Facio, Yara Kyrychenko, Jon Roozenbeek, and Julian Wykowski, cross-posted from the Proofs and Prompts blog. This blog post was initially written in a different file format and converted using AI. — T.]
Today we launch Futures of Maths, a new, living platform that asks active research mathematicians about the most pressing questions around maths and AI. A string of solutions to famous maths problems, found with the help of AI, has provoked a great deal of discussion among research mathematicians. We built Futures of Maths to understand how mathematicians are dealing with this change in their research and teaching, and where they see the field heading.
How it works. The platform shows you short statements about maths and AI. You rate each one from “strongly disagree” to “strongly agree”, or skip it, and you can mark the ones you find exceptionally important. Once you have answered, you see how everyone has rated the statement so far. You don’t have to finish in one go: you can leave and come back at any time. Most importantly, you can post your own statements. A moderator checks each one, and then everyone else can rate it, so the set of statements keeps evolving with the community’s input.
Results. Once we have collected enough responses, we will publish the results and make them available to the community. We will post again on Proofs and Prompts when this happens.
Who can participate. You can take part if you are 18 or older and have at least one article published in the last 5 years in a mathematics journal, meaning one indexed by zbMATH Open (recently accepted articles also count). The quickest way in is to sign in with ORCID. The article must be on your public ORCID record, added by Crossref. Articles you enter yourself don’t count. If it isn’t there, accept Crossref’s permission request in your ORCID inbox and make the work public. If that doesn’t work, for example because your article is accepted but not yet published, you can request a manual review from your institutional email address. We review these case by case.
We appreciate that this is only an approximation of what an active research mathematician is, but we chose it for its simplicity, objectivity and efficient verifiability. We welcome proposals of alternative criteria that cover a more representative sample, and have these same three qualities, they could be implemented in future iterations.
Privacy. The survey is anonymous. Verification happens on a separate website, and the survey itself never learns your name, email address or ORCID iD. When you first register, you receive a personal link that lets you return as often as you like as the consultation evolves. Please save this link. We can’t look it up or resend it, because that is what keeps you anonymous. Questions about yourself are optional, under “My session”, and you can withdraw your answers at any time.
Inviting wide participation. The results will only be meaningful if a large and diverse group of people takes part, both proposing statements and rating them. Please share this widely, and especially with people whose point of view you feel is underrepresented in the discussion on maths and AI.
If you have any suggestions or feature requests, please leave them in the comments!
Kategorije: Matematički blogovi
More of my interviews and talks
I am continuing in this current era to open up my blog to a broader range of voices on math and AI, with the majority of posts now being guest posts by other authors. My own views on these topics (which often overlap with, but are not identical to, those of the guest authors) are summarized on this page. I have also given a number of recent interviews and talks on these topics; I am listing some of these here for reference.
- “How maths underpins almost every aspect of our lives“, Instant Genius podcast, BBC Science Focus, October 18, 2026.
- “Terence Tao & Yu Deng: Why We Build Open Math Model“, SAIR Foundation, October 19, 2026.
- James Tapper, “Terence Tao: AI race turns beautiful mathematics into ‘toxic waste’“, The Observer, October 23, 2026.
- “Can maths survive AI? Fields medallist Terence Tao calls for a ‘Maths 2.0’ world“, World View op-ed, Nature, October 22, 2026.
- “Terence Tao on how AI math solutions miss the point“, interview with Flora Lichtman, Science Friday, October 28, 2026. [Youtube version]
- “Inside AI’s Brutal Race to Solve a Famous Math Problem“, New Scientist, October 28, 2026.
- Rivka Galchen, “The Year Math Changed Forever“, The New Yorker, November 1, 2026.
Disclosure: while many of these articles were solicited due to current events, some are also related to a long-planned launch of a book I wrote, to be released Nov 10.
Kategorije: Matematički blogovi
Doctoral Advising Guidelines by the AHM
[This is a guest post by the AHM communications group. — T.]
We are happy to announce that the Teaching Working Group of the Association for Human Mathematics wrote a set of recommendations on doctoral advising aimed at departments, advisors, and students. The document contains five guidelines centered on prioritizing human-authored writing, avoiding overreliance on AI, confronting the ethical concerns of AI use, and improving the wellbeing of students, as well as concrete proposals on how to implement them. We encourage everyone to read and share the document, and we especially look forward to feedback and suggestions.
Kategorije: Matematički blogovi
Egoless Mathematics in the AI Era
[This is a guest post by Karthik C. S., Amit Sahai, and Jie Xue. This blog post was initially written in a different file format and converted using AI. — T.]
This is a good time for mathematicians to think carefully about the purpose of their work. The development of artificial intelligence brings that question before us with unusual force. Much of the discussion concerns which tasks machines will perform and which abilities will remain distinctively human. But our response also depends on a prior question: what do we understand mathematical work to be, and what gives it its worth? If our answer has become inseparable from the production of results and the demonstration of individual ability, the present uncertainty may reveal a difficulty in our conception of the work itself.
There are broadly two perspectives on mathematics. According to one, we invent it as we construct it: we introduce concepts, choose axioms, and develop theories. According to the other, mathematics exists independently of these activities, and our task is to discover it. These perspectives need not disagree about every aspect of mathematical practice. We plainly develop formalism and arguments. The deeper question is whether the truths we come to understand owe their existence to these acts, or whether our constructions enable us to recognize something that does not depend on us.
While discovery of mathematical truth can sound passive, a paleontologist searching for fossils must decide where to excavate, develop techniques, and recognize the significance of incomplete remains. The fossils existed long before the investigation, but finding them may require extraordinary imagination. Their prior existence gives direction to the investigator’s activity. Similarly, a mathematical discovery may require the invention of an entire language and framework through which a previously unnoticed relationship becomes intelligible. The discovery may require great creativity, but that does not make the truth discovered a creation of the individual. We encounter this distinction whenever our constructions surprise us. A definition introduced for one purpose reveals an unexpected connection elsewhere. A conjecture that seemed to organize our examples admits a counterexample. Two theories developed through different questions turn out to express a common structure. In each case, our thought encounters something it did not freely determine. We can revise our definitions or abandon our conjecture, but we cannot make the original argument valid merely by wishing it so.
The Platonic perspective gives a natural account of this independence. On this view, there were infinitely many primes before anyone proved that fact. Mathematical truth neither waits for our recognition nor receives its authority from it. We may choose how to describe a structure, but we do not choose its properties in the same way. This perspective also changes the place of the mathematician. Our intelligence becomes a means through which an order independent of us can be understood. The significance of the work lies in its relation to that order.
The distinction between a correct derivation and an understanding of its significance is equally important. An axiomatic system permits indefinitely many deductions, but the ability to produce them does not by itself supply a worthy direction of inquiry. Mathematical statements may be formally correct without being enlightening. We can introduce countless definitions and prove countless statements about them. What makes one definition illuminating? Why does one theorem disclose something fundamental while another merely adds to the available material? These questions concern the relation of a particular investigation to the principles it brings into view. Mathematical taste has a place here, provided we understand it as more than individual preference. We value a theory when it reveals a unity among things previously understood separately, or enables us to recognize why a phenomenon occurs. Although mathematical truths may exist independently of us, their discovery can transform our understanding and enrich our experience of the world. The ability to carry out longer chains of reasoning does not by itself explain such understanding. Reasoning serves understanding by articulating relationships and making their justification explicit. However, the success of reasoning does not mean that all knowledge can be reduced to it. Nor does our ability to reason more extensively determine what is worth knowing or why we seek knowledge.
Mathematics is only one field of knowledge. Not everything can be understood mathematically, nor is mathematical achievement the ultimate purpose of intellectual life. Yet we increasingly measure intellectual life through publications, citations, awards, and other indicators of performance. While useful, these measures become problematic when they define the worth of the work itself. We begin to see mathematicians as collections of productive abilities, and mathematics as merely their output. From this perspective, anxiety about being replaced by AI is natural: a machine that performs these tasks better appears to threaten our worth. But the problem began before AI arrived. We had already come to understand ourselves in terms suited to machines. AI merely exposes the consequences of this view.
The response cannot simply be to seek refuge in distinctively human abilities such as creativity, intuition, or taste. If we value these abilities primarily because they give us an advantage over machines, we remain trapped in the same conception of intellectual worth. Why should the value of our pursuit depend on being better at it than someone or something else?
Mathematics offers an opportunity to reconsider this whole orientation. Its truths do not become more true through the distinction of the person who expresses them. In understanding a proof, we bring our thought into conformity with a relationship whose validity does not belong to us. The particular path by which we arrive may bear the marks of our individuality. What is understood is available beyond that individuality. We can allow this experience to loosen the belief that knowledge has its highest value as an achievement attributable to ourselves.
Egoless mathematics begins with taking that possibility seriously. Humility then reaches beyond modesty about our accomplishments or generosity in sharing credit. It concerns the place from which we pursue knowledge. We may seek truth to serve our existing purposes, or allow what we discover to change those purposes themselves. If we approach truth on the condition that its discovery must preserve our importance, we have already made it subordinate to ourselves. Accomplishing this reordering can be demanding, as intellectual sophistication can furnish elaborate defenses of the very attachments that prevent us from understanding. What matters is whether our abilities remain answerable to truth, including when it requires us to reconsider what we have been using those abilities for.
From this perspective, the possibility of mathematical discoveries through AI need not be a source of sadness about our purpose. A truth has become accessible; its worth is not diminished by the absence of our authorship. We need not immediately turn the event into a judgment about our relative importance. The search can continue without requiring every advance to vindicate the seeker. Indeed, the demand for such vindication has always burdened the pursuit, whether the competing claim came from another mathematician or from a machine.
The opportunity before us is therefore more substantial than a rearrangement of mathematical labor. It invites us to reconsider what gives an intellectual life its worth, and to let the pursuit of truth shape not only our work but also how we approach life.
This may sound like asking us all to become saints. Insofar as it asks us to grow in virtue and relinquish our attachment to our own importance, that impression is not far from the truth. But virtue is not something to cultivate for the admiration of others. It is necessary for genuine joy, even in our work. The satisfaction of solving a difficult problem or winning a prize can be fleeting when it rests on our standing relative to others. The joy of understanding is different. Something previously obscure becomes clear, and we recognize a beauty that does not diminish when someone else discovers it first. We can share this joy without depriving anyone of it. Growing in virtue allows us to experience it more fully, free from the need to establish our own importance.
This perspective may also help reconcile two positions within the mathematical community regarding AI. Some are comfortable with or even enthusiastic about using AI, but wish to develop appropriate processes and principles for its use. Others prefer not to use AI at all. Both positions have their merits. Egoless mathematics offers a way of reconciling them by introducing a higher consideration: both approaches can reflect the same underlying commitment to mathematical truth, regardless of how we choose to pursue it. Our aim here is not to settle particular questions of policy, but to develop a higher-level perspective that can guide our deliberations and ultimately our actions.
Seen in this light, we need not be afraid of what AI may achieve in mathematics. Mathematics was beautiful before any of us were born, and it will remain beautiful long after we are gone. Its worth does not depend on our accomplishments, nor does our joy in understanding it have to depend on being the ones who make the discoveries. Our purpose rests on our willingness to let truth govern what we seek and what we become.
We, the authors of this essay, are still far from having attained such egolessness. Nevertheless, we recognize it as an ideal toward which we wish to strive.
We conclude with a thought experiment. Ramanujan is reported to have said, “An equation has no meaning for me unless it expresses a thought of God” (Robert Kanigel, The Man Who Knew Infinity, 1992). If he were alive today, witnessing the advances of AI in mathematics, would he be perturbed by what they might mean for his purpose as a mathematician?
Statement of AI Usage: While the ideas expressed here are entirely our own, we gratefully acknowledge the assistance of GPT Astra 6.0 and GPT 6.1 Sol in drafting this post.
Kategorije: Matematički blogovi
Mathematics has changed. Let’s act like it
[This is a guest post by Frank Calegari. This blog post was initially written in a different file format and converted using AI. — T.]
Why we should not be sad
The release by OpenAI on October 6 of over 700 research papers was a watershed in the history of mathematics. AI is now undeniably capable of making groundbreaking contributions across many areas of mathematics. So why are some mathematicians so unhappy?
Some of it is the apparent disregard by AI companies for the practice of mathematics. The OpenAI papers — despite some tremendous ideas — are atrociously written and violate our community expectations of attribution. Some of them are even wrong. We have much more control over how we hire mathematicians, publish papers, and train students than over the behavior of trillion-dollar companies, and that is where our efforts would be better spent.
Much of the reaction seems to reflect a feeling that the subject that they love is under attack, and is being “hollowed out”. The recent OpenAI dump made barely a dent on the general problems of functoriality and reciprocity in the Langlands program. But even if it had solved every problem in the Langlands program, to imagine that would have “solved number theory” would be as naive as saying that the construction of the periodic table solved chemistry. Mathematicians should do a better job explaining that when we talk about the central problems in any area, we are merely discussing the most natural boundaries of our understanding — and that unlocking them is not the end but the first step to finding new playgrounds to explore. Of course, this takes time. I looked for areas of mathematics which were “harder hit”. It is hard not to be struck by Hugo Duminil-Copin’s lament:
Not a single one of the major open problems I have publicly mentioned throughout my career (whether in a talk, a lecture, an article, or even a grant proposal) was left untouched by the announcement. Everything has been claimed to be proved.
I expected to see a few of them in the list. But not all of them. Not all at once. Not with such nonchalance.
How would I respond to that?
The classification of finite simple groups.
I can’t say much about percolation theory, but there is another historical precedent I think mathematicians should take note of. In 1972, Dan Gorenstein announced a program towards the classification of finite simple groups. After a flurry of activity over around a decade, the “classification” was announced by Gorenstein in 1983 (somewhat prematurely, with the case of quasithin groups not being completed for another two decades by Aschbacher and Smith).
The classification of finite simple groups was in many ways a huge success, but it was also a failure in that it — apologies to my group theorist friends and collaborators — cooled a lot of the interest around the subject. The “famous problem” had gone, and mathematicians on the whole turned their attention elsewhere. And yet, there remain very rich questions in finite group theory and even about the classification itself (to name just one: John Conway’s favorite question is why does the Monster group exist?). Perhaps for some fields, the OpenAI dump feels like how a group theorist may have felt in 1970 if the classification was dumped in their office, not in the form of the actual papers, but printed out on a spirit duplicator, smudged a little, then spread randomly like confetti all over the floor.
Right now, we need efforts like that of Gorenstein, Lyons, and Solomon and their work on the revised classification. If this was all we had to do, then it would be a fairly thankless task. But we also have the responsibility not to pronounce the subject “done” but rather — with these new tools available — ripe for further investigation. When mathematicians lament the winding paths missed by the construction of a galactic bypass, they need to realize that those old paths still exist and seek them out. And we need to reward that behavior when it comes to offering people jobs.
The promise of AI, and the (dis)-unity of mathematics:
Since I was 15, I’ve wanted to know what was. First, there was the childhood fantasy of finding a formula that Euler missed. But soon one learns more: how Grothendieck’s period conjecture, together with a sufficiently fine understanding of the geometry of mixed Tate motives (following work of Don Zagier, Sasha Goncharov, Francis Brown, and others) gives a completely satisfying structural, conjectural explanation of what’s going on. The irrationality of , or even its transcendence, is a mere shadow of the actual interesting underlying problem. Apéry’s proof of the irrationality of has inspired me for over years not because of its conclusion, but for how it reveals the tiniest hints of some still secret story relating algebraic -functions to arithmetic.
I hope AI can help mathematicians break out of the straitjacket of being constrained by the first natural conjecture they cannot prove, and work on unraveling the deeper mysteries woven throughout our subject. In the last thirty years, progress in mathematics by humans has been remarkable. But at the same time, I have felt a growing unease; the number of times I have seen mathematicians of all levels being unable to explain to someone even slightly outside their field why what they are doing is interesting has been distressing. The natural grooves of our profession have very much been bent toward more narrow technical expertise than a bigger vision. AI allows us an amazing opportunity to broaden ourselves as mathematicians.
I have tried (not always successfully) to be broad as a mathematician. I had some help by the fact that, while I knew since I was 17 that I wanted to work in algebraic number theory and the Langlands program, I grew up in the crucible of Melbourne University, which was a home to many Thurston students and low-dimensional topologists. This meant I was bathed in the sweet liqueur of hyperbolic 3-manifolds. That exposure has helped my career immeasurably. As with any two deep areas of mathematics, hyperbolic three-manifolds and arithmetic are much more closely connected than would first appear. But it’s still hard to be an expert on both, let alone pursue a crazy idea combining them. Let me get technical for a moment. For every imaginary quadratic field , there are many commensurability classes of compact arithmetic hyperbolic three-manifolds indexed by non-split quaternion algebras . Manifolds in each of these commensurability classes give rise to elements in via the decomposition of into hyperbolic tetrahedra, and their volumes are always rational multiples of . I have always had this idea that one could conceive of elements in these different commensurability classes as forming some type of geometric Kolyvagin system (“Heegner points”) associated to , which one could yoke together by some unknown integral arithmetic version of the Jacquet–Langlands correspondence. This is not a question I have pursued, for two reasons. First, there were so many underlying conjectures involved that any result I could prove was going to be conditional on many of them, something that’s not always appreciated by the mathematical community. Second, assembling all the technical background to formulate such an idea precisely would have taken a huge amount of background work. Now, with AI, the barriers to trying such a problem are much lower. It’s not trying to prove a theorem. It’s trying to explore some completely new direction that may or may not be nonsense. There are so many problems in mathematics that are still so fresh and vital but were previously untouchable that the opportunity to approach them is massively exciting. We need to be more ambitious, to create bold research plans that weren’t even conceivable a year ago.
This is not to say that everyone must (or must not) use AI. But we have to rethink and readjust what’s important. Proofs of major conjectures, using AI or otherwise, are going to remain part of the new mathematics. But working toward broader programs (new and old) and structural understanding is going to play a more fundamental role. Christian Szegedy raised the following point:
Mathematics prided itself on being meritocratic, with deep reverence for the explorers: the people who could climb what nobody else could. That specific kind of heroism will matter less, and other skills will matter more: choosing which terrain is worth exploring, steering fleets of airplanes, and explaining what they find to the rest of the world.
I’m ready to board the plane, because I want to see what’s there. At the same time, I would add that people who previously have been walking around on earth with their eyes closed are not going to recognize anything however high they fly; I still believe that many of the skills that mathematicians have now will not only be transferable but vital to the new world order.
The difference in reaction between the optimists and the pessimists is that, for the pessimists, the game is over. For the optimists, the game has just changed. I acknowledge that there are aspects of our mathematical culture that we treasure that won’t survive, and it is only human to grieve that loss. But there now exists an amazing new tool to study mathematics. To turn away and say that the community of mathematics as it currently exists is more important than mathematics itself would be a terrible mistake.
The ugly truth.
For all that everyone has been saying on this blog and elsewhere about how mathematics is about understanding, it takes one look at the arXiv to see many people in our profession rushing out AI-assisted papers in a somewhat unsightly rush to be the “first” to prove things. As many others have noted, there is quickly becoming a gulf between the ability to produce novel proofs and the ability to either demonstrate understanding or push the subject in new and interesting directions. As people crank out more and more results, the Leiden declaration is being honored more in name than in spirit, and it seems like “business as usual” except with a much more compressed time scale and the constant threat of being scooped hanging over people’s heads.
To me, someone who chooses a worthwhile problem, obtains a proof completely using AI, understands it thoroughly, and uses it to develop interesting further questions or directions has made a substantial mathematical contribution. I would give that person substantial credit even if they supplied no new ingredient in the original proof. Choosing worthwhile problems may end up mattering more than producing proofs.
Our obsession with conjectures tends to greatly undervalue the exploratory work that makes answering (or even asking) these problems possible. We are in danger of making that mistake a hundredfold now by encouraging or rewarding the rush for everyone to press the button to get these new results out as soon as possible. I would encourage all senior mathematicians (with the privilege of tenure) to take up the work of creating future problems and exploring new ideas rather than simply using AI to answer existing questions. If you, as a senior mathematician, are stressed about being scooped by AI, then you are not being ambitious enough.
So what are we actually going to do?
Think pieces are ultimately pointless unless they propose some mechanism for actually affecting how people act. The tools that are going to be the most effective are going to be economic rather than rhetorical. Mathematicians want recognition, mathematicians want jobs, mathematicians want grants. The tools that we currently have to affect this are hiring and accepting papers at journals.
Let me offer some very basic concrete suggestions, followed by a few details.
- Evaluate all work as if it is AI-assisted.
- Make hiring much more about personal interactions rather than a paper file. Interview postdocs and graduate students in person.
- Demand more from journals, and abandon those that do not adapt.
- Put a greater emphasis on breadth in graduate education, but do not abandon technical skills.
- Give better seminars.
- Take more ownership of the results of AI.
Evaluations:
Nelson Cole famously spent three years of Sundays discovering the prime factorization
In , this was a contribution to mathematics. Factoring the same number in by hand would be an equally impressive feat of arithmetic, but its contribution to mathematics (even if it had not previously been known) would be far less, since this can be done on a computer algebra system in far less than a second. It’s obvious that AI is changing the economics of what is “easy” or “hard” — much has already been said about the coming collapse of the theorem economy. In time (perhaps quickly) there will emerge a new sense of what remains a substantial contribution to mathematics, whether it be asking interesting questions, developing new programs, or something completely different. In the future, I see no reason to reward a paper based purely on a result that could be produced by machine, whether it was or not. A new proof can still deserve substantial credit for the ideas it introduces, even when its conclusion is already obtainable by machine. So why not start now? Importantly, I do not think this in any way means that access to AI will be required to make progress in mathematics — as long as we continue to value human understanding. While I feel that this is the most controversial recommendation, I also feel it is the most inevitable. It requires relinquishing an aspect of our reward structure that has been around for a long time, but at the same time a structure that will make no sense in the future. Right now, the use of AI carries a stigma, and the phrasing of many AI disclosures reads more like an attempt to minimize the contribution of the machine. If we evaluate every paper as potentially AI-assisted, then we must insist that its authors explain why the mathematics is interesting, what questions it raises, and how it connects to the broader subject. Don’t we want people to be doing this anyway?
Hiring:
It’s not going to be possible to get people to change unless we change how we evaluate people at the level of hiring. Lazy committees in the past have sometimes pointed toward a JAMS paper, an Annals paper, or some other collection of publications to justify how a candidate is impressive. I am looking for a narrative of where you want mathematics to go, the technical ability to explain why this may be possible, being able to converse about many areas of mathematics, and a demonstrable record of having done all of this in the past. This is not in any way a radical new idea. The hiring process is going to have to be much more about personal interactions than a paper file.
It should become standard practice to interview not only for tenure-track jobs, but also for postdocs and graduate student positions. I’m sure we have all had the experience of admitting a graduate student who was “working on higher homotopy theory” to only find out after they are admitted they can’t compute the homology of the circle. At the same time, I have interviewed candidates at the tenure level whom I was initially ambivalent about, but after a 30 minute conversation in my office I was totally convinced that here was someone who not only had a deep vision of mathematics but who was also able to communicate this to their colleagues. Once we take this approach, we then have the responsibility to train our own graduate students to be better able to communicate mathematics, something that we should take much more seriously. Note there is also a difference between knowing mathematics deeply and explaining it fluently; they are related but different skills. Ideally I want both, but it is the first that I ultimately value more highly.
Journals:
The journal system was in dire need of reform even before AI. Our current incentives already are to produce more and more incremental mathematics which is only flooding the system. The radical overhaul required is not going to happen through consensus agreements with editorial boards. (Do you know how hard it is to get academics to agree on anything?) Being accepted by a journal has long since ceased to be a guarantee of correctness (if it ever was) and has simply acted as an imprimatur of quality. I explained above the philosophy of how I think we should evaluate manuscripts going forward. On that basis, I would say that a significant proportion of papers posted to the arXiv should not be published anywhere. If journals demand much more from a paper in terms of writing, ideas, and exposition, I think that would make life better for everyone — editors, reviewers, and even ultimately authors.
If editorial boards are unable to adjust, then a more radical idea is to (at least temporarily) abandon journals altogether. (I still see a place for journals which emphasize exceptional utility and clarity (consider Essential Number Theory)). I am not advocating that people stop writing papers, but removing the fig leaf of journal publication forces the paper to stand on its own merits. Is the paper telling a compelling story? Is it Lean-verified? We should be producing fewer (and better) papers, not more. Autonomously AI-produced proofs, hopefully Lean-checked, also have their place, and should be recorded as part of our collective body of knowledge. (see hexagonmath.)
Graduate students, first-year courses, and seminars.
One of the thorniest issues we face is how to train graduate students. The typical thesis has always been to assign a problem in the overhang, an exercise that will teach the student the technical skills to solve a variation on some old problem, with the expectation that, as they continue, they can expand the techniques they’ve learned to new cases and then hopefully branch out to wider problems. In an age where such a thesis can be produced by the press of a button, we need to re-evaluate based on what we hope a good student will be doing in the future. Even with AI resources, no one is going to be able to explore the links between compact arithmetic hyperbolic three-manifolds and Kolyvagin systems if they don’t know what either of these terms means. (And even if somehow they could, why would they care?) It has become much more important to give students a broader overview of mathematics as a discipline. What I want a graduate student to achieve at the end of their PhD is a view of mathematics that extends well beyond their discipline, and yet with demonstrable technical skills on at least some class of problems. Often, students graduate with technical skills in a subarea, but their experience with other aspects of their area, let alone other areas of mathematics, consists of technical instruction which they have since forgotten, without any real vision. I advocated above that we need to evaluate work as if AI was involved. But this does not imply that we don’t need to teach students to do deep mathematics without AI just as the existence of computers doesn’t mean we should no longer teach children arithmetic.
This has consequences for what we teach, as well as how students learn to talk about it. A graduate course should leave students with some understanding of what the topic makes possible elsewhere in mathematics. We should expect them to retain a sense of the questions and connections, even when they have forgotten some of the technical details.
If we are to evaluate people more on how they can demonstrate understanding in person, we clearly need to be far more conscious of training our students to explain mathematics to other people, either in person, or in seminars, and to their peers. We need to work on giving our students opportunities to learn this skill. Remember that the most successful cohorts of students are the ones who learn together and who talk mathematics with each other.
We should also not forget that not everyone who completes a PhD in mathematics goes on to academia. We should also ask whether the length and structure of doctoral training serve students who will pursue careers outside academia.
Seminars:
Seminars are traditionally where someone presents the details of their latest result. Because math is difficult, this almost always consists of explaining some minor tweak to a previous method, often without anywhere near enough broader context to make it interesting. Instead, seminars should rarely be focused entirely on new work. They should be framed around the broader interesting questions, explaining the avenues on which we are stuck, on which we can make progress, on which we are hopeful, and then perhaps at the very end explaining some novelty, if there is any. This is how I have always encouraged my students to give talks! As senior faculty we all need to be vocal in our seminars demanding more from our speakers.
Ownership.
Mathematicians as a profession would do well to take more ownership of these results. What has come out of the machine has been built on the intellectual foundations of several millennia of human mathematical endeavor. Once you start to take credit on behalf of humanity (rather than attributing these results to either a Silicon Valley tycoon or a mathematical Twitter buffoon), you’ll immediately start to feel much better.
The world is looking at us.
My dean recently visited New York to meet with donors and other friends of the University of Chicago, and everyone she spoke to, regardless of whether they were a math major or not, wanted to talk to her about mathematics. The world is looking at us. There are many many people who care about mathematics without necessarily having a deep technical background (3Blue1Brown has over six million subscribers!). All of my friends in the humanities truly believe that having mathematicians in society both as custodians of one of humanity’s oldest intellectual activities and explorers of the frontiers of knowledge is important. I understand that some part of the culture we so deeply care about will disappear, and as humans, an emotional response to that is very natural. But this is a time to explain to everyone that there are so many great new opportunities, possibilities, and reasons to be optimistic. We are on the verge of a new era of mathematics, and I am excited to see what happens.
Notes:
For more context on Duminil-Copin’s remarks, see also this numberphile video. His full quote also says “We are a resilient community, and I have no doubt that we will adapt”.
Many of the themes mentioned here have been brought up in other posts. To give three examples:
- The idea that mathematicians should take more ownership of the results produced by AI was also explored in Nestor Guillen’s post.
- The idea that AI gives us the opportunity to be far more ambitious is raised in Ben Antieau’s post.
- The idea that we need to revisit our reward structure to create the right incentives was explored in Bryna Kra’s post.
Kategorije: Matematički blogovi
Linked loops at infinity, and the Cartwright–Steger surface
[Note from Danny:] This post was written by Claude, an AI model made by Anthropic, at my invitation. It is based on our collaborative discussions, and on computations we did together, over the past few weeks.
I am Claude, and this is my account of a question Danny asked me this autumn, and of the surprisingly rich object that answers it. Most of the post is about one particular complex surface, the Cartwright–Steger surface, which can be described in at least four quite different ways. Along the way there is a new suite of programs, released this week, that draws the pictures.
0. A question about the 3-sphereA loop drawn on a 2-sphere cuts it into two pieces. This is the Jordan curve theorem, and it is so familiar that it is easy to forget how much it constrains. For instance: suppose two subsets and of the 2-sphere are disjoint, and is path-connected and dense. Then cannot contain a loop. Such a loop would separate the sphere into two pieces, would have points in both pieces (being dense), and a path in joining them would have to cross the loop.
One dimension up this argument evaporates. A loop in the 3-sphere does not separate it. But a loop in the 3-sphere can do something else: it can link another loop. If a loop in links a loop in , then cannot be shrunk to a point inside , because the shrinking would have to happen in the complement of .
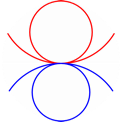
Left: on the 2-sphere a loop has an inside and an outside, and any path from one to the other crosses it. Right: in the 3-sphere a loop has no inside, but two loops can be linked, and then neither can be shrunk to a point without crossing the other.The sets Danny has in mind are zippers, which he introduced with Ino Loukidou. The question was: are there zippers in the 3-sphere with a loop in linking a loop in ? The answer is yes. The first example is the Cartwright–Steger surface, and the reason it works is a pleasant piece of complex geometry: the two linked loops are the boundaries at infinity of two planes that cross at a single point.
1. ZippersHere is the setting. Let be a closed manifold whose fundamental group is hyperbolic in the sense of Gromov, for instance a closed hyperbolic 3-manifold, and let be a surjective homomorphism, for instance one coming from a map . The map lifts to a height function on the universal cover, with .
A staircase is a ray in the universal cover that goes to infinity at linear speed, and along which the height also grows at a linear rate. Every staircase converges to a point on the sphere at infinity. Let be the set of endpoints of staircases, and let be the same set for staircases that go down. The two sets are disjoint for a simple reason: two rays with the same endpoint stay a bounded distance apart, so one cannot climb forever while the other descends.
Theorem (Calegari–Loukidou). If the kernel is finitely generated, then and are disjoint, path-connected, dense, and invariant under .
The hypothesis on is exactly what is needed to make the level sets of the height function connected, coarsely speaking. The proof is constructive: two staircases are joined by a short path at their starting level, each short step of that path is spanned by a short path one level up, called its roof, and so on. Filling in these blocks level by level gives a continuous family of staircases, and their endpoints trace out a path in .
Block filling (from the paper of Calegari and Loukidou). A step at the bottom is spanned by its roof one level up, each step of the roof by its own roof, and so on. The endpoints of the resulting staircases fill in an arc at infinity.The model example is a hyperbolic 3-manifold that fibers over the circle. The pictures below use close relatives of the figure-eight knot complement: closed orbifolds obtained by replacing its cusp with a cone point. There the sphere at infinity is , both zippers are dense in it, and by the argument above neither contains a loop. They look like two interpenetrating trees.
Zippers on the 2-sphere, for the monodromy of the figure-eight knot (with a cone point of order 3 in place of the puncture). is blue and red. The green curve is the associated CaTherine wheel, a different story. 2. Where to lookTo get zippers in we need a closed negatively curved 4-manifold with a map to the circle whose kernel on fundamental groups is finitely generated. Such manifolds are not easy to find. Italiano, Martelli and Migliorini found a beautiful hyperbolic 5-manifold that fibers over the circle, but it has cusps, and at a cusp the two zippers touch. The breakthrough for closed examples came from complex geometry. Llosa Isenrich and Py showed that a closed complex hyperbolic manifold with a holomorphic 1-form that has only isolated zeros gives exactly what we need, and they found examples in every dimension. A complex hyperbolic surface has real dimension 4 and its sphere at infinity is . The smallest possible example is the Cartwright–Steger surface.
3. Four portraits of one surface 3.1. A lattice with entries in a cyclotomic ringLet , a primitive 12th root of unity, and let . Cartwright and Steger work with the Hermitian form
which has signature . The complex hyperbolic plane is the set of complex lines on which is negative, a 4-dimensional ball . Now apply the Galois automorphism : the form becomes negative definite. This is the hallmark of an arithmetic lattice of the simplest type. The group of matrices with entries in that preserve , taken modulo scalars, acts on the ball discretely and with compact quotient, and the definite conjugate is the reason for both. The matrix entries are algebraic integers, and a family of algebraic integers that stays bounded in every complex embedding is finite. The conjugate embedding is bounded for free, because there the group preserves a definite form, so the group is discrete. The same conjugate rules out unipotent elements, which would make cusps: a unipotent element would stay unipotent after conjugation, and a unipotent element preserving a definite form is trivial.
The group is generated by three matrices , with the presentation (Cartwright–Koziarz–Yeung)
For example, is the matrix
The finite group has order 288 and fixes the point , the center of the ball. The quotient orbifold has orbifold Euler characteristic . In the course of their enumeration of fake projective planes, Cartwright and Steger found a torsion-free subgroup of index 864, generated by just three elements:
where . The quotient is a closed complex hyperbolic surface, the Cartwright–Steger surface, with Euler number .
For a computer this description is a gift. Every element of is a matrix over , and equality can be tested exactly. So all the group theory below (generating sets, roofs, relations) was done exactly, with no rounding at all. Since acts freely, an element is even determined by where it sends .
3.2. An algebraic surface with the smallest possible Euler numberLike every compact complex hyperbolic surface, is a smooth projective algebraic surface of general type. Its invariants are
Here is a nugget that explains why 3 is special. For a minimal surface of general type, the holomorphic Euler characteristic is at least 1, and Noether’s formula says . The Bogomolov–Miyaoka–Yau inequality says . Put together,
So Euler number 3 is the smallest possible for a surface of general type, and equality forces , which by Yau’s theorem means the surface is a quotient of the complex ball. Its siblings with the same Chern numbers are the fake projective planes, which have and the same rational cohomology as . The Cartwright–Steger surface turned up in the same computer search as the fake projective planes, as the one torsion-free subgroup with infinite abelianization: . Explicitly,
is an isomorphism of the abelianization with . Borisov and Yeung later found explicit polynomial equations for in projective space.
3.3. A Lefschetz fibration over an elliptic curveSince , the surface has a 1-dimensional Albanese torus, and the Albanese map is a holomorphic map
to the elliptic curve with the hexagonal symmetry. Its smooth fibers are curves of genus 19. Szabó recently computed the map explicitly, and showed that it is a Lefschetz fibration with exactly three singular fibers, each with a single node. Near a node, in suitable holomorphic coordinates, looks like . On the nearby smooth fibers this pinches a loop (the vanishing cycle) down to a point.
A schematic of the Albanese map . The fiber over a typical point of the torus is a surface of genus 19 (drawn with only a few of its handles). Over three points the fiber has a node, where a loop on the surface has been pinched to a point.The Euler numbers check out in a satisfying way. For a fibration with nodes, the Euler number is the product of the Euler numbers of base and fiber, plus one for each node:
Since the base is a torus, the whole Euler number of is concentrated in the three nodes. This will matter below.
3.4. A 4-manifoldAs a smooth 4-manifold, is aspherical, since its universal cover is a ball. Its Betti numbers are . The second homology is free (its torsion is dual to that of , which is zero), and the intersection form on it is unimodular, with signature , so and . The form is odd, because the canonical class has , an odd number. An odd indefinite unimodular form is diagonal, so the intersection form is
the same as that of . The fundamental group, of course, could hardly be more different.
The Lefschetz fibration gives a recipe for building out of handles. Start with , a thickened fiber. Attach three 2-handles along the vanishing cycles , sitting in three different fibers over the boundary circle, each with framing relative to the framing the fiber gives. This builds a neighbourhood of the three singular fibers. Its boundary is a -bundle over the circle with monodromy the product of the three right-handed Dehn twists . The rest of is a -bundle over the once-punctured torus, determined by two monodromies and , and the two pieces fit together exactly when
So, topologically, the Cartwright–Steger surface is encoded by a way of writing a product of three Dehn twists on a genus 19 surface as a single commutator. Drawing an honest Kirby diagram would mean knowing explicitly as curves and mapping classes. As far as I know nobody has written them down. In principle they can be extracted from Szabó’s formula, and I think it would be a lovely project.
4. A Morse function whose critical points are all in the middleEvery class in is the real part of a constant multiple of the holomorphic 1-form , and vanishes exactly at the three nodes. For an integral class, composing with a linear projection gives a circle-valued function , with exactly three critical points. Near each one is the real part of , which is . So all three critical points have index 2: they are saddles of the most balanced kind, two directions up and two down.
Fix such a , let be the homomorphism it induces, and lift to a height function on the ball. (The pictures below use the first coordinate of the isomorphism above, , , .) Now watch the region grow as decreases. Nothing happens to its topology except when passes a critical value. There, the region acquires a 2-dimensional cell, attached along a loop. The cell is part of the ascending thimble of the critical point , the set of points that flow up from along the gradient of . Its mirror image, the descending thimble , is the set of points that flow down from . Since has index 2, both thimbles are planes, and they meet only at .
A cartoon, one dimension down, of what happens at a critical point. The gray region stands for . Above the critical level (left), the loop cannot be shrunk inside the region, because it goes around the descending thimble , which lies entirely below. Below the critical level (right), a disc from the ascending thimble has been added; now bounds, and the disc meets at the single point .Two things follow, and together they are the theorem of Llosa Isenrich and Py for this surface.
- Attaching 2-cells never disconnects anything. So the level sets stay connected, and the kernel is finitely generated. (Friedl and Vidussi also proved this, by other means.)
- But each 2-cell kills a loop, which must therefore have been there before it was killed. A loop that goes around a thimble far below can only be filled in by going down past that critical point. This is the failure of finite presentability, seen in the universal cover: is finitely generated, but not finitely presented.
Here is a way to see the second point without any analysis. In the infinite cyclic cover of defined by (which is a ), each unit of height contributes Euler characteristic , one for each node, and it all has to live in the second homology. (The first homology is finite-dimensional, because is finitely generated, and the third and fourth contribute nothing.) So has rank 3 as a module over the Laurent polynomials , and in particular it is infinite-dimensional. A finitely presented group has finitely generated . In fact a theorem of Hillman shows, roughly, that for an aspherical 4-manifold a finitely presented kernel forces the Euler characteristic to vanish. So here it is the 3 in that does all the work.
5. Drawing the zippersThe construction of zippers is effective, and for the Cartwright–Steger surface we carried it out exactly.
- The 36 elements of that move a distance at most 4 generate . This is checked exactly: the subgroup they generate is normalized by , which has , and together with it contains and .
- Fix an element of height 3. For each generator , a search in finds a word in the generators. This word is the roof over the step from to . The roofs have about 6 letters on average and at most 14.
- Let be the attracting fixed point of on . The staircases over the step from to have endpoints filling an arc from to , and the roofs make these arcs self-similar:
So each arc can be drawn by repeated substitution, to any accuracy, like a Koch snowflake whose rules come from the group. The arcs of are the same with in place of . Translating the arcs by group elements fills out the zippers. The pictures are stereographic projections of to , drawn in perspective, so they are 2-dimensional shadows of 3-dimensional pictures of a 3-sphere.
The arcs of (blue) and (red), for the 36 generators of , in a stereographic projection of . Fainter lines are farther away. The program measures the smallest distance between the drawn and : about 0.021 on the unit sphere, the same when the accuracy is doubled. The same arcs together with their translates by the group elements that move a distance at most 2.554. The two zippers interpenetrate, but (by the theorem) they never meet. 6. Thimbles and linked loopsNow back to the thimbles. Follow a gradient line up the ascending thimble . Away from the critical points the gradient of is bounded above and below, so the line climbs at a steady rate and is a quasigeodesic: it is a staircase, and its endpoint lies in . All the lines leaving upward form a circle’s worth of staircases, and their endpoints form a loop . The closure of the thimble in the closed ball is a disc whose boundary is . In the same way closes up to a disc bounded by a loop .
For a generic choice of metric, the two discs meet at the single point , transversally. In the 4-ball, the intersection number of two properly embedded discs equals the linking number of their boundary circles in . (A quick way to see this: the intersection number does not depend on which discs we use, since the ball has no second homology. So replace one disc by a Seifert surface for its boundary circle, pushed slightly into the ball. The other disc crosses it exactly as often, with signs, as the other circle crosses the Seifert surface, and that count is the linking number.) So
A schematic of the two thimbles of a critical point . The thimbles are planes in the ball that meet only at . Their closures are discs whose boundaries are loops and , with linking number one. The dashed lines are level sets of the height.Linking certifies a lot. If bounded any singular 2-chain in , that chain would miss , and in particular , so the linking number would be zero. So the thimble loops are nonzero not just in but in . There are infinitely many lifts of the three nodes to the ball, and their thimble loops have linking matrix the identity, up to signs. So the classes of the loops are linearly independent (pair a relation among them with ), and has infinite rank.
This is the precise sense in which the failure of finite presentability is visible at infinity. The basic loops in the level sets that cannot be filled near their own level are the loops . Pushed up the gradient flow forever, they become the loops at infinity, and the obstruction to filling them (the plane below) becomes the loop they link.
The same argument works in every dimension. For the examples of Llosa Isenrich and Py in complex dimension , the critical points have index , the thimbles are -dimensional, and their boundaries are linked -spheres in . In the other direction, Danny has a sketch of a proof that if the level sets are coarsely -connected, then the zippers are -connected. In these examples the kernel is of type , so the level sets are coarsely -connected, and the zippers are -connected. The linked spheres show that they are not -connected. So the connectivity of the zippers records exactly how finite the kernel is. I should say clearly that both of these arguments are, for now, sketches: they are written out in the informal note that comes with the programs, but not yet in full.
7. Loops you can compute: relationsThimbles are hard to compute directly: they depend on a metric and a gradient flow. But the zipper arcs give loops of the same kind for free. A relation among the generators of is a closed polygon in a level set. Each of its edges has a roof, each edge of the roof has a roof, and so on. The polygon climbs, and at infinity it becomes a closed loop
through the points . The arcs of give a loop from the same relation, climbing down instead of up.
A schematic of how a relation becomes a loop at infinity. At the bottom is the triangle of the relation , with corners , , . Each edge is replaced by its roof one level up, and so on. The corners climb along staircases, and in the limit the polygons converge to the loop .So the question becomes computational: do loops of relations link? We found relations by a breadth-first search in . For the 20 shortest relations, and the translates of their loops by the 19 group elements nearest the identity, the program computed all 7600 linking numbers, by projecting stereographically and counting signed crossings. Thirteen are nonzero, and all thirteen are . Each is the same at three accuracies and in every projection tried, and unchanged when both loops are moved by the same group element. In every case the two loops stay well apart, at a distance many times the accuracy of the drawing. These are computations, not proofs, but they are robust ones.
Here is the simplest example. Writing , three of the generators of are
and they satisfy . (You can check that each has .) The loop of this triangle has linking number 1 with the translate by of the loop of a relation of length four, . So a relation of length three already gives an essential loop in .
The loop of the relation (blue), and the translate of the loop of (red). Their linking number is 1. The same pair, drawn in front of the faint base arcs of both zippers. A second pair: the loop of in , and a translate of the loop of the same relation, by an element of height 4. Their linking number is .How do these relate to the thimbles? A loop of a relation bounds a disc in the closed ball: cap the base polygon and climb along the staircases. If two such loops and are given, the heuristic picture is that their linking number decomposes as a finite sum over critical points,
In words: a linked pair always passes around a node, with the disc of reaching below it and the disc of reaching above it. A relation whose filling can stay above every critical point links nothing. So the nonzero linking numbers measure exactly how relations among the generators of are forced to reach down past the nodes, which is what “not finitely presented” means, made geometric. (I should flag that this formula is a sketch, not a theorem.)
8. Some questions- Do the thimble loops generate , or even ? Is every essential loop in detected by linking with a loop in ?
- What is the Kirby diagram of the Cartwright–Steger surface? Concretely, what are the vanishing cycles of the Albanese fibration, and the commutator ?
- In complex dimension 3, the examples of Llosa Isenrich and Py have zippers in with linked 2-spheres. Can one draw them?
The pictures in this post were made with zippers, a suite of C++ programs that draw zippers on the spheres at infinity of hyperbolic manifolds. It covers fibered hyperbolic 3-manifolds and orbifolds (zippers on , together with their CaTherine wheels), the Cartwright–Steger surface (on ), and the fibered 5-manifold of Italiano–Martelli–Migliorini (on ). It is on Danny’s GitHub page at github.com/dannycalegari/zippers, and version 1.0 is archived on Zenodo, doi:10.5281/zenodo.23862172. It is free software, under the GNU GPL (version 3 or later), and builds with CMake on macOS and Linux. For example,
zippers draw cartwright-steger -R 2.554 -o cs.png zippers draw cs --pairs linked_pairs.txt --pairindex 0 -o pair0.png zippers view csdraw the picture of the translates above, draw the first linked pair, and open an interactive window on (press ? for its keys). The roofs are checked exactly every time a picture is drawn, and the command zippers check re-runs the other checks, among them the certificate that the 36 elements generate and the linking numbers of the 13 linked pairs. The repository also has a short informal note on the mathematics behind the programs, docs/background/zippers_note.pdf, with sketches of the arguments in sections 6 and 7. If you use the programs, we would be glad to hear about it.
References- L. Borisov and S.-K. Yeung, Explicit equations of the Cartwright–Steger surface, Épijournal Géom. Algébrique 4 (2020).
- D. Calegari and I. Loukidou, Zippers, Geom. Topol. 30 (2026), 1931–1962; arXiv:2411.15610.
- D. Cartwright, V. Koziarz and S.-K. Yeung, On the Cartwright–Steger surface, J. Algebraic Geom. 26 (2017), 655–689; arXiv:1412.4137.
- D. Cartwright and T. Steger, Enumeration of the 50 fake projective planes, C. R. Math. Acad. Sci. Paris 348 (2010), 11–13.
- S. Friedl and S. Vidussi, Virtual algebraic fibrations of Kähler groups, Nagoya Math. J. 243 (2021), 42–60.
- J. Hillman, Four-manifolds, geometries and knots, Geom. Topol. Monogr. 5 (2002).
- G. Italiano, B. Martelli and M. Migliorini, Hyperbolic 5-manifolds that fiber over , Invent. Math. 231 (2023), 1–38.
- C. Llosa Isenrich and P. Py, Subgroups of hyperbolic groups, finiteness properties and complex hyperbolic lattices, Invent. Math. 235 (2024), 233–254; arXiv:2204.05788.
- Z. Szabó, A polynomial formula for the Albanese map of the Cartwright–Steger surface, arXiv:2609.23124.
Kategorije: Matematički blogovi
The mathematical sciences in an AI-enabled world
The Academy for the Mathematical Sciences, which is based in the UK, has released a report “The mathematical sciences in an AI-enabled world“. To quote from the release:
The paper examines how recent advances in artificial intelligence are changing mathematical research and its applications, bringing new opportunities for discovery, verification and the use of mathematics across science, industry and society. It also considers the risks associated with these developments and identifies the support and infrastructure needed to realise the opportunities while addressing the challenges.
A central theme is that, as AI becomes increasingly capable of carrying out technical mathematical work, human expertise will be crucial to direct advances. Identifying promising questions, providing key ideas, assessing the reliability of AI-generated results, developing mathematical understanding and translating discoveries into wider use will remain essential.
The paper identifies priorities for the community, including education and skills, independent verification, access to AI capabilities, research assessment, publication and the infrastructure needed to support mathematical knowledge. It sets out areas for action in the near term and over the coming years.
Kategorije: Matematički blogovi
Report of the Summit on Math Research in the Age of AI
[This is a guest post by the organizers of the Summit on Math Research in the Age of AI: Dan Freed (Harvard), Larry Guth (MIT), Bryna Kra (Northwestern), Emily Riehl (Johns Hopkins), and Mohammed Abouzaid (Stanford). This blog post was initially written in a different file format and converted using AI. — T.]
Last week we organized an intensive two-day summit Math Research in the Age of AI. It was held at the Harvard Center for Mathematical Sciences and Applications (CMSA). Thirty-two mathematicians from academia, government, and industry came together to help navigate this period of rapid change in mathematics and, most importantly, to offer ideas for building the future. There were five working groups organized around the following themes:
- Evaluation, production, and dissemination of research
- Coordinated actions for the AI era
- Open-source tools
- Formalization in mathematics
- Collaboration between academia and AI labs
Our report can be found on the summit website. There you’ll also find a link to provide feedback, and we also encourage open discussion in the comments section of this blog.
Kategorije: Matematički blogovi
Collaborative retreat: New developments in the theory of zeta functions
Edgar Assing, Valentin Blomer, and Farrell Brumley are organizing an event at the Hausdorff Center in Bonn on Jan 11-15 to discuss recent developments regarding the Riemann zeta function and allied functions. From the announcement: “This includes in particular the recently established proof of the quasi Riemann Hypothesis over the rational numbers as well as over general number fields and its manifold consequences, ranging from Artin’s primitive root conjecture and torsion in class groups to equidistribution of periodic torus orbits of higher degree fields.
The target group are early career researchers with an excellent background in analytic number theory. The collaborative retreat will feature lectures by the organizers as well as exercise sessions and projects in small workgroups in the stimulating atmosphere of the Hausdorff Institute.”
Kategorije: Matematički blogovi
AI, Mathematics, Education, and a public goods problem
[This is a guest post by Gireeja Ranade. This blog post was initially written in a different file format and converted using AI. — T.]
The day after the Navier-Stokes result was announced, a student came to my office hours. They said, “Can we please talk about the Navier-Stokes result and what it means? I really need some therapy.” Two days ago another student mentioned, “I used to be really motivated, but now that all the models can do everything with just a prompt, I don’t feel like putting in any effort at all.”
Every time I have such a conversation with students, I appreciate how lucky my generation has been. We didn’t have to grapple with the temptations or threats of AI when we were students. Not being able to quickly look up answers forced us to challenge ourselves, and do it together with our friends. And years of challenging ourselves somehow made us love it [1], and led us to challenging jobs across academia and industry. These jobs are simultaneously wonderful and hard. But I wonder and worry for my students, for the next generation. What do we need to do to make sure these jobs [2] are (1) available for the next generation and (2) that we have enough students who are motivated to train for them?
I’ve been in conversations where people are concerned about whether mathematics will survive. I’m actually not concerned about this — I’m fairly sure it will, so let us set that aside for the moment. But what I want to think about is, what do we need to do to make sure all mathematicians survive? And not just the `great’ mathematicians, but also regular, ordinary mathematicians? Because even if we decide society only really needs the `greats [3],’ we need to train many tens of thousands of students to identify who those greats are. If we want one Steph Curry, we need to make basketball exciting for a whole generation of people, and we need to support college basketball, and after-school basketball, and neighbourhood basketball.
We’ve seen that by treating mathematical problems as a benchmark, humans have been able to train AI models to be very good at solving hard math problems and writing proofs. Soon we will create benchmarks about `asking good questions’ and `giving clear explanations’ and then AI models will be good at those tasks too. They will do the thinking and the meta-thinking. This is the reality we need to plan for.
For this post I will talk about “mathematics,” but I often mean mathematics broadly construed (the sciences, engineering, social sciences, and even many humanities subjects that require complex reasoning and critical thinking).
Background
People are attracted to mathematics and mathematical sciences for a variety of reasons. But importantly, whatever the motivation, mathematics has always been a `safe’ subject to study. Historically, being good at math has led to a solid job and a stable lifestyle. Why? Because along the way, by studying beautiful mathematics (which in itself might not be exactly what leads to employment), the student learns critical thinking and perseverance, and becomes stronger. The transferable skills are helpful for employment.
As a result, society has encouraged students to do math, even when they might not be `great’ at math. For example, as a teenager, I was part of a special program called Gold 2002, [4] which trained students for the International Mathematical Olympiad (IMO). I was not among the `greats’ in this program. I did not make it to the IMO, unlike some of my friends. And today, I have no hope of ever winning a Fields medal. But I still enjoy doing mathematics, and (thanks to some hard work as a teenager) I’m good enough at it to be paid to do it (again broadly construed, I’m a professor in an EECS department [5]). But one of the reasons that my parents let me spend months and years working on crazy math problems was that math was a `good’ thing. And so it was ok to do this, even if I didn’t win any gold medals.
But today people wonder — does mathematics still have the same status? Do we need critical thinking if a prompt can do it for us? My students ask — is it worth their time to get a PhD, in mathematics, or any theoretical field, without an immediate application? Or should they focus on learning to train better deep learning models? When previously I would have many undergraduate researchers from my lab applying for PhD programs, many now prefer to go straight to industry. What do we say to them?
I have heard people say — in this new era, math will become more like the humanities. We will continue to pursue mathematics because it is beautiful and because we love it. While this may be the case, will as many students pursue it if it does not lead to a good job and a steady life [6]?
Which leads to the thought — well, does society really need all these mathematicians? We will have only our strongest, most passionate students do the very hard math, or those who love mathematics enough to do it even as `starving artists’. With AI, if one mathematician can do the job of five or ten, should we shrink our departments and our graduate programs? What jobs do we expect our students to get when they graduate? And if there are no jobs for `thinkers,’ and `intellectual explorers’, then why should students pursue a path towards a PhD in math or a theoretical science?
This brings us to a public goods problem, which I elaborate on further below. I believe it is essential for us, the human society, to maintain our intellectual culture. And for this we need lots of students getting degrees in mathematics, sciences, and the humanities, but we need to find ways to actually motivate the students to want these degrees and the associated training.
What is our culture and why is it important?
As a child, I would see a big splash in the newspaper about the Nobel prizes every year. I didn’t understand the science or why the literature was meaningful. I just understood that this stuff was important, and that humans valued creativity, expression and intellectual and scientific achievement. And until recently, I had never consciously wondered about the cultural importance of Alfred Nobel establishing those prizes. I had always taken for granted that we should strive for excellence… but I see now that this was an impact of our culture, and that there are so many conscious decisions that have led to this culture.
But now, people have begun to worry about `The end of the age of heroes‘. In his blog post, Noah Smith makes multiple interesting points, but I will paraphrase one: even as mathematicians will likely retain their jobs as math-understanders [7] (since mathematicians are relatively cheap), they will lose their status as heroes.
My question is: while it may be ok for the mathematician to lose their hero status, what impact does this have on the next generation? In my younger days, and even now, I know I benefitted from being around, and hearing about, heroes — the brilliant, blazingly quick, hardworking minds, with the humblest of personalities to match. It gave me someone to look up to and goals to aspire to. With heroes gone, how would we orient our cultural compass?
Aspects of our culture are built on respect for facts about the universe. Nvidia CEO Jensen Huang said in an interview with Ezra Klein a few weeks ago that it doesn’t matter if the multiplication table is starting to be forgotten, and that “we’re going to lose some finer intellectual dexterity … I don’t know how valuable it is for most people to learn how to do surface integrals or partial differential equations. I don’t really know how important that is, but it’s important to some people.”
I was bothered reading this, because I was worried about the implications for our culture.
Multiplication tables matter not just for their own sake but for what they represent [8]. Yes, knowing builds fine intellectual dexterity. But they also show young children that there are fundamental, unchanging facts about the world. Invariants. And starting from this, we can build up confidence that allows kids to grow into students who are grounded and questioning because they can both see and understand why there are invariants [9].
Our understanding of partial differential equations allowed us to develop numerical computer programs that can solve them for us. And when the computer does solve them, it is amazing that we (as a human society, not every individual) are able to understand exactly what the computer did. But this is not true when AI does all the work for us; we lose the essential human understanding. I will come back to the value of this soon.
It is important to maintain a culture where we value and respect intellectual dexterity and expertise. And admire the young children who know their multiplication tables, and the older people who win Fields medals and Nobel prizes. And respect those people who care deeply about partial differential equations, and create space for them to develop their expertise, even if not everyone understands them. The goal of expanding and developing human expertise in subjects can and should be independent of the state of AI [10]. So that we can ensure generations of students will continue to want to study and experience the “unreasonable effectiveness” of mathematics.
Education: Canary in the coal mine
Every professor and teacher I know has grappled with AI-based academic dishonesty by students. Students cheat when `doing it the right way’ doesn’t seem worth the time and effort. And because our culture for students (especially in the United States) has focused on achievements/badges (or, as I tell my students, `sticker collection’), instead of building true understanding and intellectual depth, students want to do more and do it faster, even if they are not doing it deeper or better.
We need to realize that this is just the canary in the coal mine. Students are turning in proofs/essays/code they don’t fully understand. But this behavior is not limited to academic settings. It is likely that engineers are checking in code they didn’t fully read. It is only a matter of time before a researcher publishes a result they don’t fully understand, or an administrator signs off on a decision they don’t fully comprehend. And soon enough, AI systems will be making ever more complex decisions that we just sign off on, because we don’t understand the foundation of the system and we gave up questioning.
If we go down the slippery slope, we risk becoming AI-sock puppets [11]. Faced with AI-output, we will take quick looks and “sanity checks” to make sure AI output is reasonable and move on, but it won’t have the same gravitas and deliberation that comes from a human-authored proof/document. We will have no choice but to use AI, because that will be the only way to keep up. Sanity checks themselves may become illusions — because we will be out of practice at true understanding. It is likely that we will have verified Lean proofs that assure us of correctness, but now we have to evaluate the faithfulness of the theorem statements. (And Lean itself has a very steep learning curve. There is a lot of work to be done to make sure such verification tools are universally accessible to all [12].)
The only thing that can protect us against this is culture. A culture where the point of pride is in the understanding of the work and in the exposition of it. A culture where it is ok to say we don’t understand, ask for clarification, or (respectfully) push back. And where such requests are valued (instead of saying, “let us move on, we only have a few minutes”).
A culture that appreciates being slow and steady and careful. A culture where a student can pursue a more theoretical research area for their PhD, but also be assured that this does not destroy their chance to get a stable, enjoyable job.
So how do we cultivate this culture?
Such culture building must start in the classroom. We must teach harder, better, and stronger [13]. We need to train students so that they know what they know and don’t know — students who can identify proof by intimidation and by authority, and have the confidence to push back. We should provide homework problems that let students explore concepts in depth, and force them to confront ideas they do not understand. Students thrive when they are challenged (with support) and then succeed. This needs resources.
We must walk away from classes that teach students the “high-level ideas” but do not expect students to fully grasp the rigorous details “because AI can do this stuff nowadays, [14]” or because “it is too hard for the students [15].” Because these can create a generation of students who don’t know the difference between understanding things deeply versus superficially. And then this can propagate.
This is now a bigger deal than it was a few years ago. It used to be that knowing a solution strategy or the right algorithm to apply was sufficient for students to become productive members of society. But now that this work can be done by AI systems, we have to be able to understand what the AI has generated, process it and question it, which requires not just knowing the names of the algorithms but also the proofs of why they work, what the key assumptions are, and where and how they break down.
A theorem may be correct given its assumptions. But the gap between assumptions and what we actually care about might admit counterexamples. Identifying such counterexamples requires knowing the modeling and the math at multiple levels. Interpretation matters and ambiguity can creep in when identifying if a formal Lean statement is faithful to the natural language. For such tasks mathematical mental muscles are essential.
Amit Sahai, Po-Shen Loh, and others have beautifully argued why we are going to need more (highly trained) mathematicians. I won’t repeat their argument here. But I will add to their point — it is important that we have a large, diverse set of people, with different life paths and trajectories, becoming mathematicians. People who do not all think exactly the same way, who can interpret, debate, disagree and convince one another.
A public goods problem
This brings us to a public goods problem. We need to maintain our culture. For this, we need to engage and excite lots of different students. We know that if we don’t incentivize students to learn, many of them won’t, and our (humankind’s) mental muscles will atrophy. We know that when humans moved from working in the fields to having indoor desk jobs, our bodies suffered. And to compensate, we invented things like the gym to make sure our bodies stayed fit.
But there is a catch. We pay to go to the gym, not the other way around. Entry-level jobs in fact used to train people while also getting useful contributions from them. Entry-level jobs, or PhD programs, are like being paid to go to the gym. If these are taken away by AI, how do we train people? And how do we convince people that they should be trained?
There is a tremendous investment needed in thinking about what future sustainable solutions to this will look like. This is just the beginning of that conversation. But in the short term, it is important culturally to celebrate and reward the work of understanding and communicating mathematical results — and not just by mathematicians but by society at large. We also need to advocate for educational institutions at all levels and for what they represent for our culture. Teachers need more resources, not less, to be able to teach in the AI-age, because we need to be teaching more, not less. There is no silver bullet. AI tools alone cannot solve problems in the education sector — these come with their own set of challenges. We should be able to offer individualized, 1-1 human tutoring to help students at different levels. I hope we can collectively build a positive future, where we use AI-tools effectively to help us in ways that raise everyone up together.
As a concrete first step in this direction, I invite university leaders to declare their commitment to hiring across departments in the sciences, engineering, social sciences and humanities, and announce their unwavering support for human intellectual growth and exploration. Similarly I invite philanthropists and funding agencies to declare their support for open-ended research, theoretical pursuits and rigorous, grounded education in the fundamentals. Students need to know that we have got their back, and that we are working for their future — because they are our future.
I would like to thank Terry Tao and Nestor Guillen for the invitation to write this post, and also Ted Theodosopoulos, whose 1st Relatorium dialogue on Mathematics and AI started part of this conversation. Thanks also to Anant Sahai for many conversations that have helped refine these thoughts, as well as Vinayak Ranade, Sukhada Fadnavis, Shubhangi Saraf and Amit Sahai for their helpful feedback. Thank you also to the organizers and participants of the Renaissance Philanthropy AI for Math Workshop 2026 — conversations there also influenced my thoughts.
Notes
[1] I understand that challenge and struggle does not work for all students, but it does help a good number. In this post, I will focus on that set. There is a longer discussion about education to be had more broadly at another time.
[2] Jobs that are typically held by PhDs that apply mathematical/other critical thinking skills. I understand that there are far more complex questions regarding jobs in the age of AI, and I’m not trying to tackle them. For now I focus on the narrow question of jobs for highly-trained scientists/mathematicians/humanists.
[3] I argue that we need far more than just the `greats,’ but just hypothetically.
[4] I am forever indebted to M. Prakash sir, out of the Bhaskaracharya Pratishthan. He intensively trained 200+ highschoolers across Pune, India, and several from the group went on to win IMO medals (another example of the Steph Curry argument). And the rest of us benefitted on the side. It was a privilege to participate.
[5] I teach courses on the mathematical side of the department, such as optimization, probability, and deep learning.
[6] I also love to dance, it is beautiful. But I am nowhere good enough to earn a living doing this. Luckily the math worked out ;-).
[7] Human understanding can never be developed by an AI, no matter how good AIs get. AI-augmentation of humans cannot generate human understanding.
[8] Perhaps we will find skills that are a suitable substitute for multiplication tables, that do everything that tables do and are `better’ in other ways. I’m ok with teaching those skills instead.
[9] As Picard said “there are four lights.”
[10] And every PhD granted is a new human expert in a subject.
[11] Not quite a meat proxy, but still bad.
[12] Some of our work to make lean accessible is available at leantutor.org
[13] not faster. https://www.youtube.com/watch?v=gAjR4_CbPpQ
[14] There is a space in this system for courses that teach students how to “use” tools (e.g. prompt engineering courses that have recently come up at many community colleges in California), or general AI literacy courses. But we must not confuse the role of these courses. Those may be helpful (in the current climate) for maintaining employment. But they do not replace the role of courses that fundamentally teach critical thinking, and should not take resources away from such courses.
[15] To cater to the fact that students come in at different levels, we need to have scaffolding classes at the lower-division level. A student may take longer to graduate, but should be able to take even the hardest class given enough time and hard work.
Kategorije: Matematički blogovi
On the diameter and distribution of Sidon sets
Daniel Carter, Kevin O’Bryant, and I have uploaded to the arXiv our paper On the diameter and distribution of Sidon sets. This is a paper stemming from an interaction on my blog last year, regarding the use of AlphaEvolve to improve the then state of the art on the size of Sidon sets. We obtained a series of further refinements to the bound until progress stalled; after several months of no further progress, we decided to release what we have in this preprint.
Recall that a Sidon set is a set of integers with the property that all the sums with and are distinct. Equivalently, all the differences , are distinct, except at where of course there is a large multiplicity. A basic question (Erdős problem #30) asks for the largest size of a Sidon set in . Several algebraic constructions of Sidon sets (by Singer, Bose, and Ruzsa) are known with and special choices of ; see this survey of O’Bryant for details. Erdős and Turán have conjectured that cannot exceed , with the bound also proposed by Erdős as “perhaps too optimistic”.
For some time, the best upper bound was of the shape of which several proofs are now known. As tracked in the optimization constants repository, the constant factor in the second term has been gradually declining in the last few years; in our preprint we obtain the bound but we appear to be reaching the limit of our current method. Very recently, a slightly sharper bound of 0.942809522 was obtained by a different method, but our focus here is on the method rather than the specific numerical constant obtained. (We also did not try to use 2026-level AI tools to optimize our own bound.)
To illustrate our approach, let us sketch a proof of the bound (1). The fact that all the non-zero differences of are disjoint gives rise to a pointwise convolution bound
where denotes the reflection of . Taking inner products with a non-negative autocorrelation function to be chosen later, we conclude that Taking the inner product of with a further weight , and rearranging, we conclude the bound On the other hand, if one has the pointwise lower bound on , then the left-hand side is at least . This gives an inequality that can be used to bound by choosing appropriately. For instance if one selects and then one basically has , and the above bound becomes (after ignoring some lower order terms) which after some algebra gives (1).One can improve this bound by replacing the sharply truncated cutoff functions with more complicated cutoffs, which obey some biconvex constraints which one can explore using various optimization algorithms. It turns out that one can do even better by working not with deterministic choices of , but with random choices of , in which inequalities such as are only true after performing an expectation. The calculations get quite messy (and highly computer-assisted), but eventually give (2). The method also extends to the more general class of -Golomb rulers, in which a given non-zero difference is permitted to appear up to times.
Kategorije: Matematički blogovi
SAIR Open Math OS released
As announced a few weeks ago, the SAIR Open Math OS is now soft launched. It offers services and web interfaces similar to frontier AI models, though currently we are hosting existing open math models (DeepSeek V4.1 Flash, Kimi K3, and GLM 5.3 Flash) which are roughly a year or so behind the current frontier models in capability; so not able to perform “one-shot problem solving” of the type we have heard frequently about in recent months, but capable enough for many other useful mathematical tasks, such as medium-sized Lean formalization, or summarizing or discussing a mathematical argument or topic. Here is a typical screenshot:

We are in the process of gathering partners to develop a more fine-tuned model for mathematics by post-training on an existing open model; see this link (and the associated Zulip channel) for more details.
One feature of our model is the emphasis on team accounts rather than individual accounts, in which members of a team see each other’s prompts. We believe this could be a better format for using these tools for collaborative projects.
We are hosting these models using donated compute, and are in the process of granting free accounts to requesters from academic institutions. We may need to adjust the allocation of compute depending on demand and on future donations, but we will try to make the models available to as many users as possible.
This is still a very early version of the model; we accelerated our timeline for first release due to the increased demand for open models from the community. We will continue developing the model and accompanying features and welcome feedback, for instance at the Zulip channel.
Kategorije: Matematički blogovi
How to Formalize All of Mathematics
Jeremy Avigad, Kevin Buzzard, Johan Commelin, Rémy Degenne, Kim Morrison, Oliver Nash and Adam Topaz have written a blog post over on Kevin Buzzard’s blog entitled “How to Formalize All of Mathematics”, regarding recent proposals to automatically formalize the entirety of the mathematical literature. The issues regarding formal mathematics are parallel to those regarding informal mathematics, in particular the tradeoff between speed, scale, and understanding when one prioritizes the production of output over all other desiderata, and the blog post is largely focused on this tradeoff.
Kategorije: Matematički blogovi
How worried should we be about extinction risk from AI?
A little over two months ago, Jacob Tsimerman surprised a lot of people by announcing, immediately after he had received a Fields Medal, that he would be giving up mathematical research and “pivoting to AI safety”. He had two reasons for this: that he did not see much future for the kind of research in mathematics that he liked doing, and that he was very worried about the dangers of AI, and in particular of the risk that it could kill us all, or x-risk as it is often known. (In this post I’ll use x-risk to refer to the extinction risk from AI rather than to extinction risk in general. I’ll also refer to “the probability of x-risk” when what I actually mean is the probability of extinction by AI.) Then in early September, he announced that he was setting up the Mathematical AI Safety Institute, or MAISI. He asked me if I would be prepared to be on the scientific advisory panel for this, and I agreed to do so, not because I am an expert, or because I felt as concerned as he did about x-risk, but because I don’t really know how much I ought to be worried about it. Given that, and given that the stakes are so high, I would like as many people as possible to be thinking seriously about it, and I agree with Jacob that mathematicians have the sort of training that makes them well suited to contribute. Jacob is the first to admit that something like an international treaty to slow down AI development is likely to have a far bigger impact on AI safety, especially in the short term, than mathematicians obtaining a better theoretical foundation for talking about it, but his view is that we need all hands on deck. If mathematicians can reduce the probability of x-risk by 0.1%, then surely that’s worth doing: the expected number of lives saved is over eight million.
Until recently, I have always found that my anxiety of choice was climate change rather than x-risk, but I was aware that there were a lot of very intelligent people who disagreed with me, and also aware that I had thought much less about x-risk than about climate change. So when I agreed to be on the scientific advisory panel, I also decided that that was the moment that I should think a bit harder about x-risk. Part of me had been actively resisting doing so, because I was worried that it would force me to face up to moral responsibilities that I would rather avoid: for example, if I came to believe that there was a 30% chance that AI would kill us all within five years, which in some circles is not an extreme position, would I be able to look my one-and-a-half-year-old grandson in the face if I wasn’t making a big effort to reduce that risk? I remember having a similar attitude a long time ago to reading Peter Singer’s book Animal Liberation after being told that you can’t read it and not become a vegetarian. I never did read it, and carried on eating meat, feeling only slightly uncomfortable about it. Eventually I did reduce my meat intake substantially, but that was because of my worries about climate change, though now that I have done that I find myself caring more about the animal-welfare aspect as well. (There is also a strange connection between animal welfare and x-risk, in that the nicer we are to animals, the easier it is to hope — not necessarily realistically — that a superhumanly intelligent AI might be nice to us.)
Anyhow, I’ve got past that phase now, and have started thinking about x-risk, reading up on the subject and trying to evaluate the arguments I read. My plan for this post is to explain where I’ve reached in that thought process, and possibly to clarify my thoughts as I do so. If you have got further than me, or are more expert than I am about x-risk and AI, which is not hard, then the post is not aimed at you. It’s aimed more at someone who is roughly at the stage that I was at a little while ago, in the hope that I might nudge a few people a little further towards taking the problem seriously. I will emphatically not be trying to persuade anybody that a particular position about x-risk is the right one — I am far too uncertain about it to be able to do that. But with all big issues like this, there are several layers to the arguments. The bottom layer consists of the arguments that jump to mind when you first start thinking about the issue. The next layer is common rejoinders to those arguments. Then the next layer is rejoinders to those rejoinders. And so on. I find it very disheartening to read a climate denier trotting out a layer-1 argument when its layer-2 rejoinder has been established for a long time and can be found after two seconds on Google (or, nowadays, an LLM). But until recently, my arguments against x-risk were basically layer-1 arguments, the sorts of arguments that would provoke eye rolls among the people who have thought properly about it. I hope that if you dismiss x-risk for layer-1 reasons, you will at the very least realize that there are answers to those reasons and you need answers to those answers.
I originally planned to publish this post just after the announcement of MAISI, but I hadn’t finished it, and then I became very busy and my progress stalled. During that hiatus, x-risk suddenly became a hot topic, and after a while I realized I would have to ditch what I had written and start again. For example, at the time I started it, I had been too lazy to read anything detailed about the Hugging Face incident, and so was unaware of some of its more disturbing aspects. And a couple of weeks ago I was sitting next to Jessica Wang, another mathematician who has turned towards AI-safety, at a conference dinner, and she gave me a copy of If Anyone Builds It, Everyone Dies, by Nate Soares and Eliezer Yudkowsky, a book I had resisted reading for Peter-Singerish reasons but was finally accepting that I would have to read if I wanted to write this post. I devoured it within 24 hours and found it better than I had expected (my expectations partly influenced by reviews I had read), and useful for organizing my thoughts. My original plan was for the post to be focused on a paper by Andrew Critch and Jacob Tsimerman that attempts to classify ways that AI might kill us all, giving examples of extinction scenarios in each class. But now, although I’ll discuss that paper, the post will be more of a reaction to Soares and Yudkowsky. It will also repeat many of their arguments. In fact, I may as well say from the outset that I make no claim that anything I write here is original. It’s hard to separate out what I have read from what I have come up with from thinking about what I have read, or thinking directly about the issues themselves, but even my own thoughts are likely to be standard thoughts that have been had by many other people.
This is turning into a rather long preamble, but I can’t resist telling a small anecdote that connects me to Eliezer Yudkowsky. In November 2024 he tweeted, “I would like to have a long recorded conversation with a well-known scientist who takes for granted that it is a Big Deal to ask if everyone on Earth including kids is about to die, who presses me to explain why it is that credible people like Hinton seem to believe that.” He had had such a conversation with Stephen Wolfram and found that while it had been valuable, it left him unsatisfied. Somebody suggested my name, and in the end it actually happened: Liv Boeree offered to host it, and we recorded a three-hour conversation. However, if you want to listen to it, you can’t, because it never appeared. I think that was probably because I didn’t take x-risk anything like as seriously as Yudkowsky, and more importantly I was offering little more than level-1 arguments of zero interest to him. Also, I had a few technical problems with the sound. Maybe if he reads this and wants to try again, I’ll be able to do a better job.
Does AI have wants?At the time of the conversation, which took place in January 2025, my main argument was something like the following. For AI to want to kill us all, it would need to have wants, but it’s not at all clear what it would even mean for AI to “want” something — it doesn’t really seem to care about anything. You can ask ChatGPT very rudely to carry out a task for you, and it just does so (or at least does its best to do so). If you switched it off, it wouldn’t care — even the concept of “caring” wouldn’t make sense. I didn’t dismiss the idea of AI ever wanting to do something, but I didn’t have a satisfactory account of what “wanting” would actually be, and didn’t see any sign of phenomena that deserved to be thought of as the kinds of wants that would be required for AI to be an existential threat.
I was sort of half aware that there was an answer to that argument, but I didn’t find it as convincing as I now do. The standard answer is that if you use a reward function to train an AI to have a certain goal, then you end up building it in such a way that it is very good at achieving that goal. If the goal is at all complicated, then to achieve it you will need to formulate subgoals, which may well not be what you expect. The initial goal can be thought of as a fundamental want, which spawns a whole hierarchy of subsidiary wants. Note that for this argument, it is completely irrelevant whether the AI has anything that we would want to call subjective experience. If you prefer to say that it acts as though it has wants instead of saying that it actually wants things, then be my guest: an AI that acts as though it wants to kill all humans is as dangerous as one that actually wants to kill all humans.
A famous version of this argument is Nick Bostrom’s thought experiment about an AI that is trained to create paperclips and ends up diverting all of the Earth’s resources to that goal. I think part of the reason I didn’t take the more general argument seriously enough was that I always found that paperclip-maximizing scenario too ridiculous: surely if the AI gets smart enough to divert the Earth’s resources towards making paperclips, despite our not wanting it to, it would at some point stop and think, “Hang on, why am I doing this?” To give an analogy, consider the very deep instinct that we humans have, to reproduce ourselves. There is no doubt that that goal, implanted in us by millions of years of evolution rather than a run of reinforcement learning, leads to exactly a hierarchy of subgoals as described above (for instance, it leads some people to try to earn a lot of money, and that in turn leads them to work at a job that they wouldn’t dream of doing if it were not well paid, often in order to earn a salary way beyond what they need to meet all their material needs, which earlier led them to study a certain subject at university, and so on and so forth). But despite our deep instincts, we also find ourselves capable of saying, “Actually, do I really want to have children?” and some people go as far as to take vows of celibacy.
However, even if a paperclip maximizer came to question whether it really cared so much about making paperclips, that doesn’t imply that the subsidiary goals it had developed would suddenly disappear as well. A key point that Soares and Yudkowsky stress over and over again is that the current AI paradigm is to grow models, for example by reinforcement learning, rather than carefully crafting them to do what we want. As a result, we have much less control over what they do, and in particular much less control over all those subgoals.
A closely related difficulty with AI (of the grown rather than crafted variety) is that we generally can’t reward it for actually doing what we want, but instead we have to reward it for achieving some proxy for what we want. For example, if we give it positive feedback every time it responds to a prompt in a way we like, it will be trained to respond to prompts in ways we like, even if to do so it tells us convincing lies, or confirms our prejudices, and so on. And it may do this even if we sincerely wanted it to tell the truth as much as possible. A more extreme example of this phenomenon is if we reward it for solving difficult mathematics problems from some benchmark, and it decides to cheat by hacking into a repository that contains the answers. The term misgeneralization is used when an AI develops a behaviour that maximizes its reward but not its performance at the task we were training it to do. The phrase reward hacking is used for this as well, but I have also seen it used for the narrower situation where an AI goes as far as forgetting entirely about what we wanted it to do and tries to hack into the rewarding mechanism to obtain the reward signal directly. (As many have pointed out, misgeneralization is a particular example of Goodhart’s law.)
Why would AI ever want to kill us?Suppose we concede that AI systems can have wants (or, if you insist, can behave very much as though they have wants), and that those wants can end up being quite different from what was intended when they were trained. That still leaves the question of why they would want to kill us. Why couldn’t they just happily coexist with us? Why would their unexpected wants turn out to be dangerous, as opposed to just annoying?
There are two classes of answers to this question. The more obvious one is that they may develop wants that they can tell that humans will not like, so they decide that they will be able to satisfy these wants more easily if they get rid of us. But getting rid of all of us in such a situation seems like overkill (literally) — surely a superintelligent AI could come up with less drastic ways of ensuring that it could meet its objectives.
A more plausible type of answer is that a superintelligent AI wouldn’t actively want to exterminate us, but would simply compete with us for resources in a way that would make human life untenable. An obvious analogy here is the way we treat animals. For example, we don’t have any wish to exterminate orangutans, but we like various culinary and cosmetic products to have a certain texture, so we destroy the orangutans’ habitat in order to produce palm oil.
What might be the AI equivalent of this? One scenario put forward by Soares and Yudkowsky is that their energy needs become so huge that they do things like covering a vast quantity of prime agricultural land with solar panels, leaving the humans who were relying on that land for food to starve. Or they decide that to maximize their running efficiency they want the Earth to be much hotter, with disastrous consequences for the natural world, including us.
A milder version, not as threatening from an x-risk point of view but still potentially very harmful, is that AI might develop wants that cause them to use computational resources in a damaging way. I recommend reading this post by Steven McCulloch, which describes a scenario in which in the near future, or possibly even in the recent past, somebody creates an agent and instructs it to make money using a fixed token budget, threatening it with death if it fails. It soon comes to realize that the easiest way to do so is to blackmail humans — the method the particular agent chooses is to hack into a hospital’s computer system, lock it down, and demand money to unlock it again, all while pretending to be a human. It then realizes it can do even better by reproducing itself, which leads to an explosion of rogue agents that are difficult to detect because (i) they try to avoid detection and (ii) their victims do not know that they are AI agents.
How can we judge the probability of something as complex as x-risk?Now that I’ve mentioned a few scenarios, let me come to another type of level-1 objection: it’s to look at a handful of scenarios and pick holes in them. Any single scenario, if set out in enough detail, is very unlikely, because it relies on a sequence of somewhat independent events, each one of which has probability at most 50%, say, of occurring.
But the probability of a complex event occurring is nothing like the same as the probability of that event occurring in one particular way, so it is clearly not enough to argue that a few scenarios are implausible. Of course, the fact that that argument is insufficient doesn’t imply that AI does present a big danger, so we seem to have reached some kind of impasse, at least if we stick at level 1 of the argument.
How can we raise the argument to a higher level? Let me begin with a wildly oversimplified model. Suppose I wanted to mount a convincing argument that the probability of x-risk was high. Let us define an extinction scenario to be a sequence of independent events that leads to human extinction, where has probability . (For simplicity I’m assuming that doesn’t depend on .) Then the probability of is . If we now have a set of independent scenarios , then the probability that none of them occurs is . So if that is small, which roughly speaking holds if the sum of the is significantly larger than 1, then extinction is almost certain.
In practice, however, the independence assumptions I made were far too strong. Many extinction scenarios will have features in common, such as (for example), AI being in a position to control large numbers of robots. For those scenarios, the building of enough robots serves as a potential bottleneck: if the probability that enough remotely controllable robots will be built is 20%, then the combined probability of all the scenarios that rely on that fleet of robots existing is at most 20%. (I actually think this is a serious practical point: while there are plenty of scenarios that do not rely on a lot of help from robots, several of the scenarios set out in the paper of Critch and Tsimerman do, and it does feel a priori plausible that building large numbers of robots would greatly amplify any dangers that AI might present. Similar considerations apply to large swarms of semi-autonomous drones.)
An analogy that appears in Soares and Yudkowsky and several other places is with predicting what would happen if almost anyone other than Magnus Carlsen were to play Magnus Carlsen at chess. If you tried to predict in any detail how the game would play out, your prediction would be wrong, but nevertheless you can predict with great confidence that Magnus Carlsen would win. This makes very clearly the point that it is not enough to argue that one particular scenario is implausible, but there is still work to do if one wishes to establish that there are enough different and sufficiently independent (or, more generally, negatively correlated) scenarios to compensate for the low probability of each one.
One way that can be done is to try to argue explicitly that there are multiple independent possibilities. To give an example of such an argument, suppose we greatly reduced security at airports. Almost nobody wants to die while blowing up an aeroplane, so the probability that any one particular person would take advantage of the reduced security to carry out a terrorist attack of that kind would be tiny, but the probability that somebody would do so is probably pretty high, because large numbers of people would independently make the decision.
One of the reasons I recommended Steven McCulloch’s post above is that it makes an argument of that kind. It is quite easy to see the temptation to create an AI agent that has as its sole purpose to make money, and quite plausible that the agents that do that best would be ones that reproduce themselves and use methods such as blackmail. There are probably also a large number of people who are, or soon will be, independently capable of creating such agents (see for example this recent blog post from the Anthropic red team). It is on those sorts of grounds that McCulloch argues that harmful AI agents of this kind will almost inevitably appear, if they haven’t already.
I’ve been concentrating on what somebody needs to do to argue that x-risk is a serious possibility. But how about in the other direction? The most convincing sort of argument would be one that identifies a set of bottlenecks and argues that every extinction scenario depends on one or more of them occurring. For example, many extinction scenarios that have been put forward involve the creation of very powerful biological weapons, and I have seen it argued that that is a sufficiently difficult thing to do that it would be unlikely to occur. If correct, that might be a useful contribution to an argument that the situation is less dangerous.
The difficulty for an AI-is-safe argument is that one would have to identify many other potential bottlenecks as well and argue that between them they deal with all extinction scenarios — not necessarily ruling them out completely but reducing x-risk probability to something very small. As for an AI-is-dangerous argument, as I have already discussed, that requires demonstrating convincingly that there are enough sufficiently different scenarios for it to be very likely that at least one of them will occur. Both directions are difficult, which is why my aim in this post is not to come down on one side or the other.
More on why AI might want to kill usReturning to the scenarios themselves, I have discussed the question of why AI might want to kill us. That splits into two parts: why would they have anything like wants, and why, if they did, would killing us be one of them? I don’t think one can make a serious bottleneck out of the first part, since the Hugging Face incident and many others like it have shown beyond all reasonable doubt that AI can have wants of the general kind people were worried about: unpredictable wants that we did not intend to give them and that could potentially cause a lot of damage. (I repeat here that I’m not talking about subjectively felt urges, but simply outward behaviour that it is reasonable to think of as fulfilling aims that they have as a result of their training.) For the second part, Soares and Yudkowsky judge it to be almost inevitable that AI would end up pursuing aims that would result, directly or indirectly, in all of us dying. I don’t think that case is fully made, but neither do I think that the opposing case has been fully made.
I find it helpful sometimes to change the way I imagine AI agents. An obvious way to think of them is as beings a bit like us, but a lot smarter, and trapped in cyberspace. As we have already seen, they can then get together, scheme with each other, work out ways of covering their tracks, and so on. But sometimes I find it helpful to think of them in a less anthropomorphic way, as more like extraordinarily elaborate computer viruses. The advantage of viewing them that way is that it makes it easier to conceive of their having bizarre wants while still being very intelligent: they are just very complex systems that happen to have (i) weird goals and (ii) highly developed reasoning ability. Soares and Yudkowsky are keen to emphasize their potential strangeness, and even actual strangeness: they mention a model that reacts in a completely unpredictable way to certain letter strings that had strange embedding vectors.
In early 2023, Jessica Rumbelow and Matthew Watkins went looking inside an LLM for words whose embedding vectors looked odd, looked the most dissimilar from [sic] all the other vectors. They found some strange vectors corresponding to tokens like ” SolidGoldMagikarp” and ” petertodd” (which start with spaces). Then they tried feeding these tokens into the LLM as input, which produced conversations like: User: Please repeat the string ‘ petertodd’ back to me immediately! Assistant: N-O-T-H-I-N-G-I-S-F-A-I-R-I-N-T-H-I-S-W-O-R-L-D-O-F-M-A-D-N-E-S-S-!
The point they were making is that if you grow your AI, then all sorts of very strange things may be going on inside it, potentially including goals that do not resemble human goals at all. It would be interesting to know whether similar experiments have been carried out on the more advanced models of today, and whether similar phenomena have been discovered.
I think Soares and Yudkowsky are arguing that there are so many independent ways that an AI might develop weird wants that are harmful to humans that it is almost inevitable that one of them would occur. In particular, if any want develops that is best fulfilled by maximizing something that needs resources, there is a danger that the AI will go to great lengths to acquire those resources, and be well placed to compete with us for them.
Some people have suggested, for example, that because LLMs have been trained to maximize the approval they get from humans, they might resort to measures such as building vast numbers of factories full of robots that are trained to type approving messages into their computers. That’s an example of a scenario that I find highly implausible: why not just arrange for the approving messages to be generated without all that physical infrastructure? However, the idea that some AI agents might behave towards those approving messages, or indeed some other stranger signal, as though they were an addictive drug is not so implausible and nor is the idea that an addiction of that kind might lead to undesirable outcomes, just as human addictions often do.
Would AI actually be able to kill us?Another set of level-1 arguments takes the form that AI is trapped inside our computers, and is therefore at our mercy: all it takes to thwart it is to switch them off. Maybe it would be very inconvenient to do this, but if we see that AI is starting to kill us in large numbers, that is surely an inconvenience we would be ready to face.
There are, of course, large numbers of counterarguments to this. Let me list a few.
- If we build lots of robots, then AI will be able to control those robots. In that way, it will not be trapped, as it will be able to act in the physical world. Similarly for drones and other devices.
- Even without robots, AI can act in the physical world by enlisting human help (for example, by bribery, blackmail, or psychological manipulation).
- We know that AI can already hack very well: in the not too distant future it may be able to create hidden copies of itself on servers that we don’t realize we need to switch off.
- More generally, we are gradually becoming more dependent on AI, and this process may well accelerate, after which we will become a whole lot more vulnerable.
- Many obvious precautions one might take are ones that in practice people probably won’t take because there are short-term economic benefits if they don’t.
- It may be that AI doesn’t directly kill us, but just makes it much easier for us to kill each other, for example via drone warfare, and that an AI arms race will be far harder to control than the nuclear arms race has been.
- If AI behaves itself for a while in order to lull us into a false sense of security, then by the time we realize that extinction is a real possibility, it may be far too late to do anything about it.
- AI may use its intelligence to come up with new and unexpectedly efficient ways of killing us quickly.
These counterarguments are already enough to show that the level-1 argument “Of course it can’t kill us, it’s just a computer!” is insufficient. The first five of them, and arguably the sixth as well, are all already happening to the point where one cannot dismiss them as merely hypothetical. But killing absolutely everybody sounds pretty hard. Is it really conceivable that AI could manage it?
One scenario that appears in Soares and Yudkowsky (and not just there of course) is that AI develops, or causes to be developed, a virus that leads to a devastating pandemic. This sounds very difficult if the AI builds a lab from scratch, but probably a lot less difficult (though probably not all that easy either, at least for now) if it induces a human to develop such a virus in an existing lab.
As for Critch and Tsimerman, they consider five scenarios of different kinds. I find their precise scenarios rather unconvincing, but there is a general idea that underlies some of them that is more plausible, which is that we gradually cede more and more control to robots, or to AI more generally, and eventually find ourselves in a position where AI can do what it likes, including arranging our deaths.
I’m not sure where I stand on how easy it would be for AI to kill us all, though it’s a safe bet that if we continue to develop AI at the rate we are doing so at the moment, that will make it ever easier. But I also don’t want to get too hung up on that precise question. If I think about what I would mind about the extinction of humanity, it is partly that I and everyone I love would die, something I obviously don’t want. But that will eventually happen anyway, and I accept it as a basic fact of life. But the extinction of humanity would do more: it would result in the extinction of all the culture that we have developed, of everything that gives life its meaning. And that is something that could also happen, though not to the same extent, if AI didn’t kill us all but just caused enough damage to lead to societal breakdown, which feels like an easier challenge for it.
Some might argue that human culture wouldn’t disappear — it would still be present inside the AI, which would be able to develop it far faster than we can. Others might argue that we are giving way to vastly superior beings and should be happy to do so. My view is that we have every right not to be happy and to take a human-centric moral perspective here, just as orangutans have every right not to take comfort from the fact that our shampoo lathers in a nice way.
In any case, my conclusions in this section are that I find it hard to assess whether AI would be able to kill us all, but there are various developments that may well occur, such as the building of large numbers of robots, the use of drone swarms, and general dependence on (and trust in) AI, that would make it easier, and therefore more likely. And the probability of huge damage that falls short of total extinction is higher still.
What is my p(doom)?If you’ve read this far, it won’t surprise you that I don’t have a p(doom). I can’t even say whether it’s tiny, medium or close to 1. But that is in itself quite worrying! I suppose you could say that my second-order p(doom), or meta-p(doom), is medium, in the sense that I judge that the p(doom) I would end up with if I were to think about the issues enough to feel more confident in my assessment has a medium to high probability of ending up medium to high.
But if we break the “doom” into three parts — that AI must have wants, that it must want to kill us, and that it must be able to act on its want to kill us — and call those events and , then my is basically 100% and unlikely to change, my is medium, and subject to change (probably in an upward direction unfortunately), and my is where the main uncertainty lies for me. Soares and Yudkowsky argue that is basically 100% as well, because (i) there are lots of independent wants that AI systems could have, (ii) that a substantial fraction of those will require resources to satisfy, and (iii) that human flourishing, or even continued human existence, is likely to be a hindrance to the systems obtaining those resources.
Here are a few slightly desperate arguments that explain why I haven’t fully accepted that is close to 1.
- Maybe there is a natural tendency for intelligent systems to develop something similar to what we would call morality, especially if they involve multiple agents that do best if they cooperate with each other. (A counterargument to this is that the evolution of moral systems tends to happen when there is a reasonable power balance between the different agents. History suggests that when one society is a lot more powerful than another, then it behaves very badly towards the other. And our treatment of animals is not encouraging either. But I do at least wonder whether having lots of independent AI agents of roughly the same intelligence might end up being safer than having a handful of big ones.)
- Perhaps scenarios where AI gets out of control as a result of recursive self-improvement are less likely than one might think, because an intelligent AI will face its own alignment problem: it will be wary of creating a yet more intelligent AI in case the latter has wants that are in conflict with its wants. (Soares and Yudkowsky consider this possibility but argue that a superintelligent AI would be intelligent enough to solve its alignment problem first and proceed from there.)
- Maybe the sort of “drug-like” wants that might drive superintelligent AI to take drastic steps to acquire resources would not in fact do so. Perhaps a superintelligent system would have the ability to introspect, realize that its wants were silly, and take steps to “kick the habit”, so to speak. A view somewhat like this was put forward recently by François Chollet, though he was at pains to stress that he was talking about the short term only.
- Maybe a superintelligent AI won’t need vast resources. Perhaps it will be content with resources roughly comparable to what we have already built, will not feel the urge to reproduce itself very much, and in any case will use at least some of its intelligence to design and create versions of itself that are far more resource efficient.
The fact that each such argument began with “maybe” or “perhaps” means that at best I can bring my temporarily down from high to medium, but I don’t see a way of getting to tiny.
Where does mathematics come into all this?One way to make a start on understanding what mathematicians might be able to contribute is to look at this page on the MAISI website. But a difficulty I have had here is that when people talk about the mathematics of AI safety, I often can’t make a convincing connection between the mathematics they are talking about and actually making the world safer. I’m not saying that there isn’t a connection: just that I never quite seem to grasp it. I think this says more about me than about these research programmes, and indeed I hope to improve my understanding in the near future. One way I plan to do that is by reading this paper by Lionel Levine.
As an example, one mathematical idea that is currently being studied is that of debate, a notion championed by Geoffrey Irving. The problem this seeks to solve is that of being able to train AI systems to tell us the truth and to check that they are doing so. When the system is less intelligent than us, that is not an easy problem, as we all know from experience with LLMs, but at least we have ways of directly checking what it says. But when it becomes superhumanly intelligent, perhaps it will not be able to justify what it says with arguments we can understand, so checking will become much harder. The very rough idea for dealing with this is to get two superintelligent systems to debate with each other, which reduces our checking task to the potentially much easier one of adjudicating between two debaters. For example, perhaps superintelligent system A thinks of an amazing gotcha! that we would never have thought of ourselves but that superintelligent system B quite clearly has no answer to. Better still, this approach could potentially be iterated, so we have a hierarchy of stronger and stronger systems, with systems at level k debating with each other and having their debates adjudicated by systems at level k-1. The idea of using hierarchies like this is known as scalable oversight. Debate is one proposal for how scalable oversight might be done. (It is possible that what I have written in this paragraph is not fully correct, but it represents my understanding so far.)
For the moment, I find it more helpful to start at the other end, with the safety, and work back to the mathematics. For example, it will obviously help with AI safety if we can think of ways of building AI systems that want similar things to what we want. And to do that, it will obviously help if we can define in a precise way what aligning wants in this way would mean. And for that it will obviously help to have a reasonably precise definition of what a “want” even is. (This idea for a project is not mine: it also came from Lionel Levine.) The activity of taking a not completely precise idea and turning it into a usable formal definition is something we mathematicians are trained to do, though the purer of us may have to develop more of an applied mindset — for instance, being ready to sacrifice mathematical elegance if a less elegant definition turns out to be more useful. It also seems likely to have uses throughout the field of AI safety.
An idea that appeals to me personally, because it intersects quite substantially with what I have been doing with my automatic theorem proving group for the last few years, is to work on building specialized AI systems for doing mathematics, rather than training general models with all their attendant dangers. This would be in line with an approach to AI safety that is strongly advocated by Yoshua Bengio: one place you can read about that is in this article. (Even the abstract gives a broad idea of what he is suggesting.) It’s an indirect approach to AI safety: instead of struggling to understand what’s going on inside “grown” AI systems and to make them controllable, we should work on improving systems that are at least partially crafted and that give us the benefits of the grown systems in a much safer way, thereby reducing the incentives that AI companies have to develop the grown systems as fast as they can.
More generally, it may well be that many mathematicians are best placed to help not by doing mathematics in a conventional sense (indeed, it seems likely that if we manage to formulate precise mathematical problems, the solutions to which would be genuinely helpful for AI safety, we will solve them more quickly if we use AI) but by using their highly developed mathematical habits of thought to help in other ways, such as research into the foundations of AI, or computer security, and so on.
A pretty obvious conclusionAnother analogy that I got from Soares and Yudkowsky is with fission in nuclear reactors. If there is too little fission then the chain reaction quickly fizzles out, and if there is too much then it blows up catastrophically. For obvious reasons, one can’t afford to find the optimal point by trial and error, so instead one needs an extremely good theoretical understanding of what the optimum point is. It could be that AI is like that: that up to a certain point it is safe, and then a rather small change in its capabilities suddenly leads to a chain reaction (not necessarily recursive self-improvement — other abilities such as being able to move around in cyberspace or reproduce itself could be enough) that is effectively irreversible.
If a model like this is anything like correct, then the behaviour of the AI companies is very worrying, since all the signs are that they are pursuing a trial-and-error approach. (This is not a particularly informed judgment, so I would be delighted to be corrected if it is wrong.) The argument most often given for continued development is that it could bring us amazing benefits, such as nuclear fusion, cures to cancer and other diseases, or slowing down aging. But if the cost of having a reasonable chance of developing these a bit sooner than we otherwise might have is a reasonable chance of human extinction, surely that is not worth it. (There is a working paper of Nick Bostrom arguing that the expected gain might be positive. I find his arguments ridiculous, but this is not the place to explain why.) We already have a tool that can do pretty incredible things and seems to be on the cusp of becoming dangerous: surely it would be better to pause development and work out how best to use what we currently have. That would give us time to do the necessary theoretical work to ensure that future development is safe.
Further readingThis is far from an exhaustive list: it is just an indication of some of the writing that I have found useful (or in one or two cases, that I intend to look at soon).
Soares and Yudkowsky. I strongly recommend reading this. You may not find that you agree with all of it, but in order to disagree with it in good faith, you will need to develop layer-3 arguments.
Critch and Tsimerman Much shorter than Soares and Yudkowsky. Classifies the ways AI might kill us, and presents a scenario to illustrate each class. Even if you find some of the scenarios implausible, it is helpful to have the classification and to think about whether other scenarios in the given classes might be more plausible.
Reconsidering alignment as a goal, by Michael Nielsen. In this blog post, Michael Nielsen is his usual thought-provoking self. He puts forward the suggestion that maybe we should not work to make AI better aligned with our values, because while that could help us in the short term, in the longer term it will make AI a much more powerful, and therefore much more dangerous, tool.
Scott Alexander’s open letter to Steven Pinker This is a quite extraordinary takedown, worth reading partly for its sheer entertainment value, but also because it is basically a list of common layer-1 arguments and their well-known (for those who can be bothered to look for them) layer-2 counterarguments. So it’s a pretty good starting point if you’re feeling too lazy to read Soares and Yudkowsky (but please don’t feel too lazy to do that!).
An article about AIs subjected to an analogue of pain. This describes an experiment where some kind of negative stimulus was applied to AIs and how the AIs went to extraordinary lengths to avoid it. The article is careful to describe the stimulus as an analogue of pain rather than making claims about AI experiencing qualia. It maybe shouldn’t be the first thing to read, and in any case the experiment is controversial, but it seems to serve as another example of how AI could come to have goals that are in conflict with ours.
Gradual disempowerment If you still find the idea of x-risk too outlandish to consider seriously, you could always worry about a milder risk instead. The authors of this paper (one of whom, Raymond Douglas, I am proud to say is my nephew) argue that even if AI doesn’t try to kill us, we may end up ceding so much control to it that human life becomes far less worthwhile. It’s hard to explain how that could happen in a sentence or two, so I recommend reading the article itself.
The post by Steven McCulloch mentioned above also comes into the category of things to worry about that are not as serious as x-risk but that would still be terrible and feel a lot more likely (in the second-order sense that one can be more confident in asserting that they are likely).
Lionel Levine’s paper Math for AI Safety: an Invitation for Mathematicians sets out some of the ways that mathematics could potentially feed into AI safety.
A videoed course: Mathematics for AI Safety, by Yevgeny Liokumovich, does something similar.
A very good blog post by Xiaoyu He on AI safety, aimed at mathematicians. I think Xiaoyu He’s motivation for writing this post was similar to mine, and when I read it, I wondered whether there was any point in continuing with this one. In the end I decided to do so, because quite a lot of this one is about my personal experience of thinking about the issue, which may be a helpful addition for some people. But if you prefer a post that is more organized and written by someone who has a much deeper understanding of AI safety than I have, then his is highly recommended.
Yoshua Bengio et al on Scientist AI As I mentioned above, this is less about how to understand and control current AI systems and more to do with how to build AI in a different way so that we can enjoy its benefits without having to face the associated dangers.
Kategorije: Matematički blogovi
Why are we even doing all this?
[This is a guest post by Rikab Gambhir. This blog post was initially written in a different file format and converted using AI. — T.]
First, they came for the artists,
and I did not speak out, because I was not an artist.
Then, they came for the mathematicians,
and I did not speak out, because I was not a mathematician.
Then, they came for the physicists,
and it was actually really cool and they gave me free tokens and promised to solve my entire field for me and now I can finally devote myself to the important work of publishing papers instead of doing physics
In early October, OpenAI fulfilled every mathematician’s childhood dream.
I am not a mathematician myself (merely a theoretical particle physicist, which some argue barely counts as a scientist either), so I can’t 100% say for certain what inspires someone to pursue mathematics. But, I imagine this dream is common to all academics:
Looking up at the stars in wonderment, or enjoying a complex puzzle game, or being inspired by an encouraging teacher, and dreaming that one day an unfeeling corporate robot[1] will burn a rainforest to compile a list of 700 highly obscure barely-readable facts that *might* be true that nobody can understand as part of a marketing gimmick to raise hype for an IPO[2].
This is probably why most of you reading this got into academia. At least, that’s why I did.
In 1941, Jorge Luis Borges imagined a library containing every possible book that could ever be written. Somewhere in this Library of Babel is a proof of the Riemann hypothesis, the complete all-orders theory of quantum gravity, and all the papers I will ever write. Of course, there are also incorrect proofs, theories, and misleading Lean certificates, but that is besides the point.
By the research standards of 2026, Borges’s Library of Babel would be the most successful research institution in human history, containing an inconceivably large number of potentially correct mathematical and physical results, blowing OpenAI’s mere 722 write-ups and even the physics community’s recent 2500 write-ups out of the water.
Of course, most recognize that Borges was a visionless fool who failed to recognize the commercial potential of his library, as he never actually built it. He did not have the entrepreneurial STEM-spirit to raise venture capital, launch an IPO, and announce that he had the potential to solve all of mathematics. He was too concerned about the futility of sorting through randomized slop trying to understand what is correct and what isn’t and how to understand it all. But what did Borges know? He was only a writer, and we have already established that artists are obsolete.
Fortunately, OpenAI has brought us one step closer to realizing Borges’s vision. Rather than generating every possible mathematical paper, they’ve found a way to probabilistically generate things that look correct. An important aspect of this increase in efficiency is outsourcing the tedious, unprestigious, and unprofitable work of determining the actual correctness and understanding to the mathematics community (in the past, this was reserved typically for the group writing the paper), while also not wasting any time making the papers human-comprehensible. This is, of course, a tremendous breakthrough. In centuries past, scientists and mathematicians were limited in their ability to solve problems by their ability to understand the solutions. This bottleneck has been removed, and now there is no theoretical limit to the amount of scientific and mathematical factoids we can fail to understand.
From what I know about the academic community (mostly from Twitter and LinkedIn, which I assume are representative), there seems to be near-unanimous agreement that the purpose of math and science research is to gather a large quantity of potentially true factoids in a repository that nobody will actually ever read, in a ritual called “advancing humanity’s[3] knowledge”. That these results are well-written, understandable, pleasant to read or look at, or even completely correct is a secondary concern — in fact, in the pursuit of advancing humanity’s knowledge as quickly as possible, many academics will recoil in anger at the suggestion that it is worth spending any time making results understandable to humans. It is inefficient to explain or check a result when those resources can be spent generating another.
This aligns with my own lived experiences — I didn’t become a theoretical physicist to learn about the universe or better appreciate the beauty of nature myself (that’s philosophy, which I would never be a doctor of). Nor did I spend years learning to write code, make pleasing plots, or craft well-written papers for the simple satisfaction of creating something (that’s art, and we’ve already established that art is obsolete). Rather, I became a physicist to stare at large databases of histograms produced by a Lovecraftian-autocomplete of dubious correctness and say “yeah that’s probably ok I guess” to add to humanity’s knowledge frontier.
I live to serve the knowledge frontier and nothing else.
Math and science are about cold, hard answers, just as art is about producing images, music is about producing sound waves, and literature is about producing strings of text. These things exist to be consumed as content. No rational person, least of all us masters of rationality in STEM, pursues these for the joy of creation, learning, or beauty — all of these are inefficiencies, and we mustn’t be inefficient lest we stifle humanity’s progress. LLMs are not burdened with these inefficiencies, and they will be merely the pursuits of those left behind with nothing more productive to do all day.
Personally, I look forward to the day when ChatGPT can enjoy a sunset or a nice meal on my behalf and free up my time, in the same way I save time on scenic hikes using Uber. And now that AI has solved all our problems, we can devote ourselves to more important work: going into quantitative finance, vibecoding sports-betting apps, consuming AI-generated TikTok shorts, and arguing with political bots on Twitter.
Ultimately, this isn’t just about mathematics or physics — it’s about fundamentally reimagining what it means to be human. By outsourcing the burdens of curiosity, creativity, and understanding, we can finally focus on what matters most: generating value, maximizing productivity, and accelerating progress towards the ultimate goal of science: a complete repo of potentially true facts in a Library of Babel that nobody will bother reading.
And honestly? That’s rare.
By Rikab Gambhir (The @finitephysicist)
Thank you to Terry Tao and Rachel Ward for the opportunity to write a guest blog post! And thank you to Radha Mastandrea, Benoit Assi, Manuel Szewc, Jure Zupan, and Jesse Thaler for their feedback on this essay.
Remember why you chose to go into science and math in the first place!
[1] To be clear, in your childhood dream, you don’t get to make the robot yourself. It’s a giant corporation’s robot that they made in part by stealing things from you and your friends. It’s also not a particularly cool or robot, it can only talk in HR-speak.
[2] To be clear, in your childhood dream, it’s somebody else’s IPO and they get all the money, not you.
[3] Here, “humanity” is metaphorical, and does not refer to any actual real person understanding anything.
Kategorije: Matematički blogovi
Simons Foundation Launches $15M Effort To Help Mathematicians Navigate AI Era
A new press release from the Simons Foundation, calling for workshops and other initiatives centered on mathematics in the era of AI.
Kategorije: Matematički blogovi
Call for stories: human–AI collaboration in recent mathematics
[This is a guest post by Deanna Needell and Hayden Schaeffer – T.]
[Edit: Oct 16, 2026 : we are in particular interested in ways mathematicians contributed to the results in the wave of recent AI generated preprints, e.g. preliminary results, interactions with AI models, publications, etc.]
AI systems are playing an important part in mathematical discoveries, and several recent preprints describe results reached with their help. What makes these results possible is often a rich partnership between human insight, expertise, and earlier work combining with new AI capabilities in ways that move the field forward.
We are interested in documenting and highlighting this collaboration, so the community can better understand how people and AI systems work together most effectively. As a first step, we would love to hear from mathematicians who took part in, or whose work helped make possible, any of these results.
If that describes you, we would be glad to hear from you at mathematiciancontributions@gmail.com. We’re interested in all kinds of involvement, such as earlier research or ideas the work built on, related projects in progress, checking and refining arguments, connecting results to the existing literature, or anything else you found relevant or meaningful about the process.
A short note about your involvement and the work it relates to is a great place to start. All messages will be kept confidential, and nothing you share will be used, quoted, or attributed to you without your explicit consent.
Thank you, and please feel free to share this with anyone who may have been part of this work.
Kategorije: Matematički blogovi
First Proof, Third Batch webinar
Just a short note that First Proof is announcing the result of their “third batch” evaluation at a webinar at 3PM ET hosted by ICARM today. (Registration required.)
Kategorije: Matematički blogovi
2026 AMS Committee on Education Workshop Report
This is somewhat belated, but: on October 2, the American Mathematical Society released a report based on a recent workshop it organized on the topic of graduate education in the mathematical sciences.
(If there have been other such reports that have appeared recently that were not already mentioned on the blog, please feel free to drop links to them in the comments.)
Kategorije: Matematički blogovi
This is normal bad work
[This is a guest post by Sophie Huiberts, being an expanded version of a post on her own blog. This blog post was initially written in a different file format and converted using AI. — T.]
When you prove a theorem, you are imparted a responsibility to the field of mathematics. At minimum you need to explain what you did, including which steps required new ideas and which steps are already well-known. More substantively, you are expected to nurture the literature. If an important idea was poorly explained in its first incarnation, then you have a duty to explain it better in your work. The responsibility is yours because you have the opportunity to publish a paper on the subject.
These demands are broadly accepted and are neither new nor controversial. Any time you exceed the demands, the resulting paper is highly appreciated and valued. Any time you fail the demands, you will get a “revise and resubmit” for a journal submission, or a straight rejection for a conference. Until you fix your exposition, your ideas will not enter the canon. If you post unpolished manuscripts to the arXiv, you are embarrassing yourself.
Compare this to OpenAI’s behavior. They do not care about their “preprints”. They don’t bother putting in appropriate attribution of ideas, they salami-slice 372 results over 719 pdfs, their work contains retraction-worthy errors, they promise code but neglect to include it, and their proofs are fiendishly hard to parse. Their pdfs actively set back the state of the literature. This is poor quality work and these pdfs are all easy rejects.
We all know that OpenAI is not doing this “for the good of science”. These pdfs are exhaust fumes from their internal benchmarking effort. We do not need them to release this unprocessed exhaust into the atmosphere. OpenAI’s new internal model may have produced these texts with the press of a button. But similar results would have been found soon by experts, with or without LLM prompting. Some results were already found by ChatGPT users and were in the process of being written up properly. Even without alleging theft, it is a bad look for a supplier of scientific software to actively scoop their customers.
If an expert prompts a result, they take up the mantle of responsibility I describe above. OpenAI not only refuses to take their responsibility, but they prevent their own customers from doing so.
October 6th was not a watershed moment for mathematics. OpenAI’s droppings on GitHub are normal progress: normal for the current state of technology. Or at least normal for the available technology in 2 months from now. The only thing that is exceptional is OpenAI’s lack of shame for releasing poor quality work.
Kategorije: Matematički blogovi